

Exploring the synergy between reinforcement learning (RL) and large-scale language models (LLM) reveals the vibrant field of computational linguistics. Although these models are primarily powered by human feedback and have shown great ability to understand and produce human-like text, they are continually evolving to capture more nuanced human preferences. Masu. A key challenge in this changing field is to enable LLM to accurately interpret and generate responses that align with subtle human intentions. Traditional methods often need to support the complexity and sensitivity required for such tasks, and advances are needed that can effectively bridge the gap between human expectations and machine output. .
Existing research on training language models includes frameworks such as Reinforcement Learning from Human Feedback (RLHF), and techniques such as Proximity Policy Optimization (PPO) to align LLMs with human intent. is used. Innovations extend to the use of Monte Carlo Tree Search (MCTS) and the integration of diffusion models for text generation, improving the quality and adaptability of model responses. This advancement in LLM training leverages a dynamic, situational approach to refine the way machines understand and produce language tailored to human feedback.
Researchers at Stanford University have introduced Direct Preference Optimization (DPO), a streamlined method for LLM. DPO simplifies RL by integrating the reward function directly within the policy output, eliminating the need for separate reward learning. This token-level Markov decision process (MDP) approach provides greater control over the language generation capabilities of the model, distinguishing it from traditional methods that require more complex and computationally expensive steps.

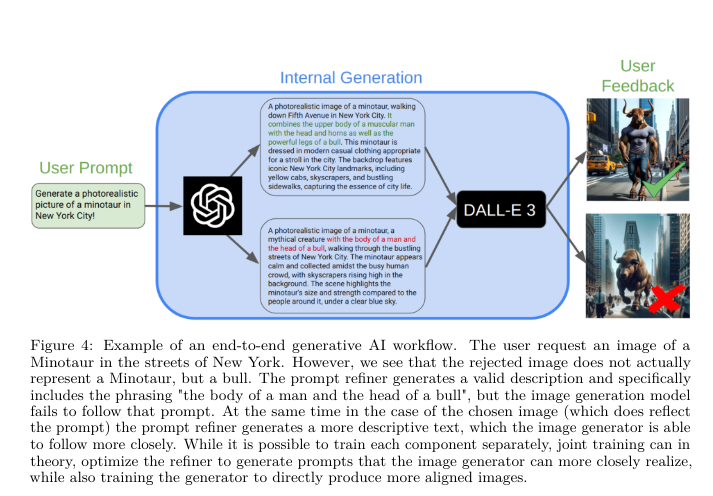
When applying DPO, the study utilized the Reddit TL;DR summary dataset to evaluate the practical effectiveness of the approach. Training and evaluation include precision-enhancing techniques such as beam search and MCTS that are specifically tuned to optimize each decision point in the model's output. These methods facilitate applying detailed and immediate feedback directly to the policy learning process, with a focus on efficiently and effectively improving the relevance of text output and alignment with human preferences. I did. This structured application demonstrates his DPO's ability to adjust language model responses in real-time interaction scenarios.
The implementation of DPO demonstrated a measurable improvement in model performance, and the study highlighted notable results. Evaluation by GPT-4 shows that when employing the beam search technique within the DPO framework, the model outperforms the base policy by 10 to 10% on 256 holdout test prompts from the Reddit TL;DR dataset. Achieved a 15% win rate improvement. This quantitative data demonstrates the effectiveness of DPO in improving the consistency and accuracy of language model responses under specific test conditions.
In conclusion, this study introduced Direct Preference Optimization (DPO), a streamlined approach for training LLMs using a token-level Markov decision process. DPO integrates the reward function directly with the policy output, avoiding the need for a separate reward learning stage. This method demonstrated a 10-15% win rate improvement using the Reddit TL;DR dataset, confirming its effectiveness in increasing language model accuracy and consistency with human feedback. These findings highlight the potential for DPOs to simplify and improve the training process for generative AI models.
Please check paper. All credit for this study goes to the researchers of this project.Don't forget to follow us twitter.Please join us telegram channel, Discord channeland linkedin groupsHmm.
If you like what we do, you'll love Newsletter..
Don't forget to join us 40,000+ ML subreddits
Learn more about content partnerships here Please fill out the form here.

Nikhil is an intern consultant at Marktechpost. He is pursuing an integrated dual degree in materials from the Indian Institute of Technology, Kharagpur. Nikhil is an AI/ML enthusiast and is constantly researching applications in areas such as biomaterials and biomedicine. With a strong background in materials science, he explores new advances and creates opportunities to contribute.