Reinforcement learning is a branch of machine learning that deals with agents that learn through experience how to interact with complex environments.
From AI agents playing complex board games like chess and Go to outperforming humans to autonomous navigation, reinforcement learning has a wide variety of interesting applications.
Notable advances in the field of reinforcement learning include DeepMind’s agent AlphaGo Zero, which can beat even a human champion at Go, and AlphaFold, which can predict complex 3D protein structures.
This guide introduces the reinforcement learning paradigm. To understand reinforcement learning frameworks, let’s take a simple but motivating real-world example.
Let’s start by defining the components of our reinforcement learning framework.
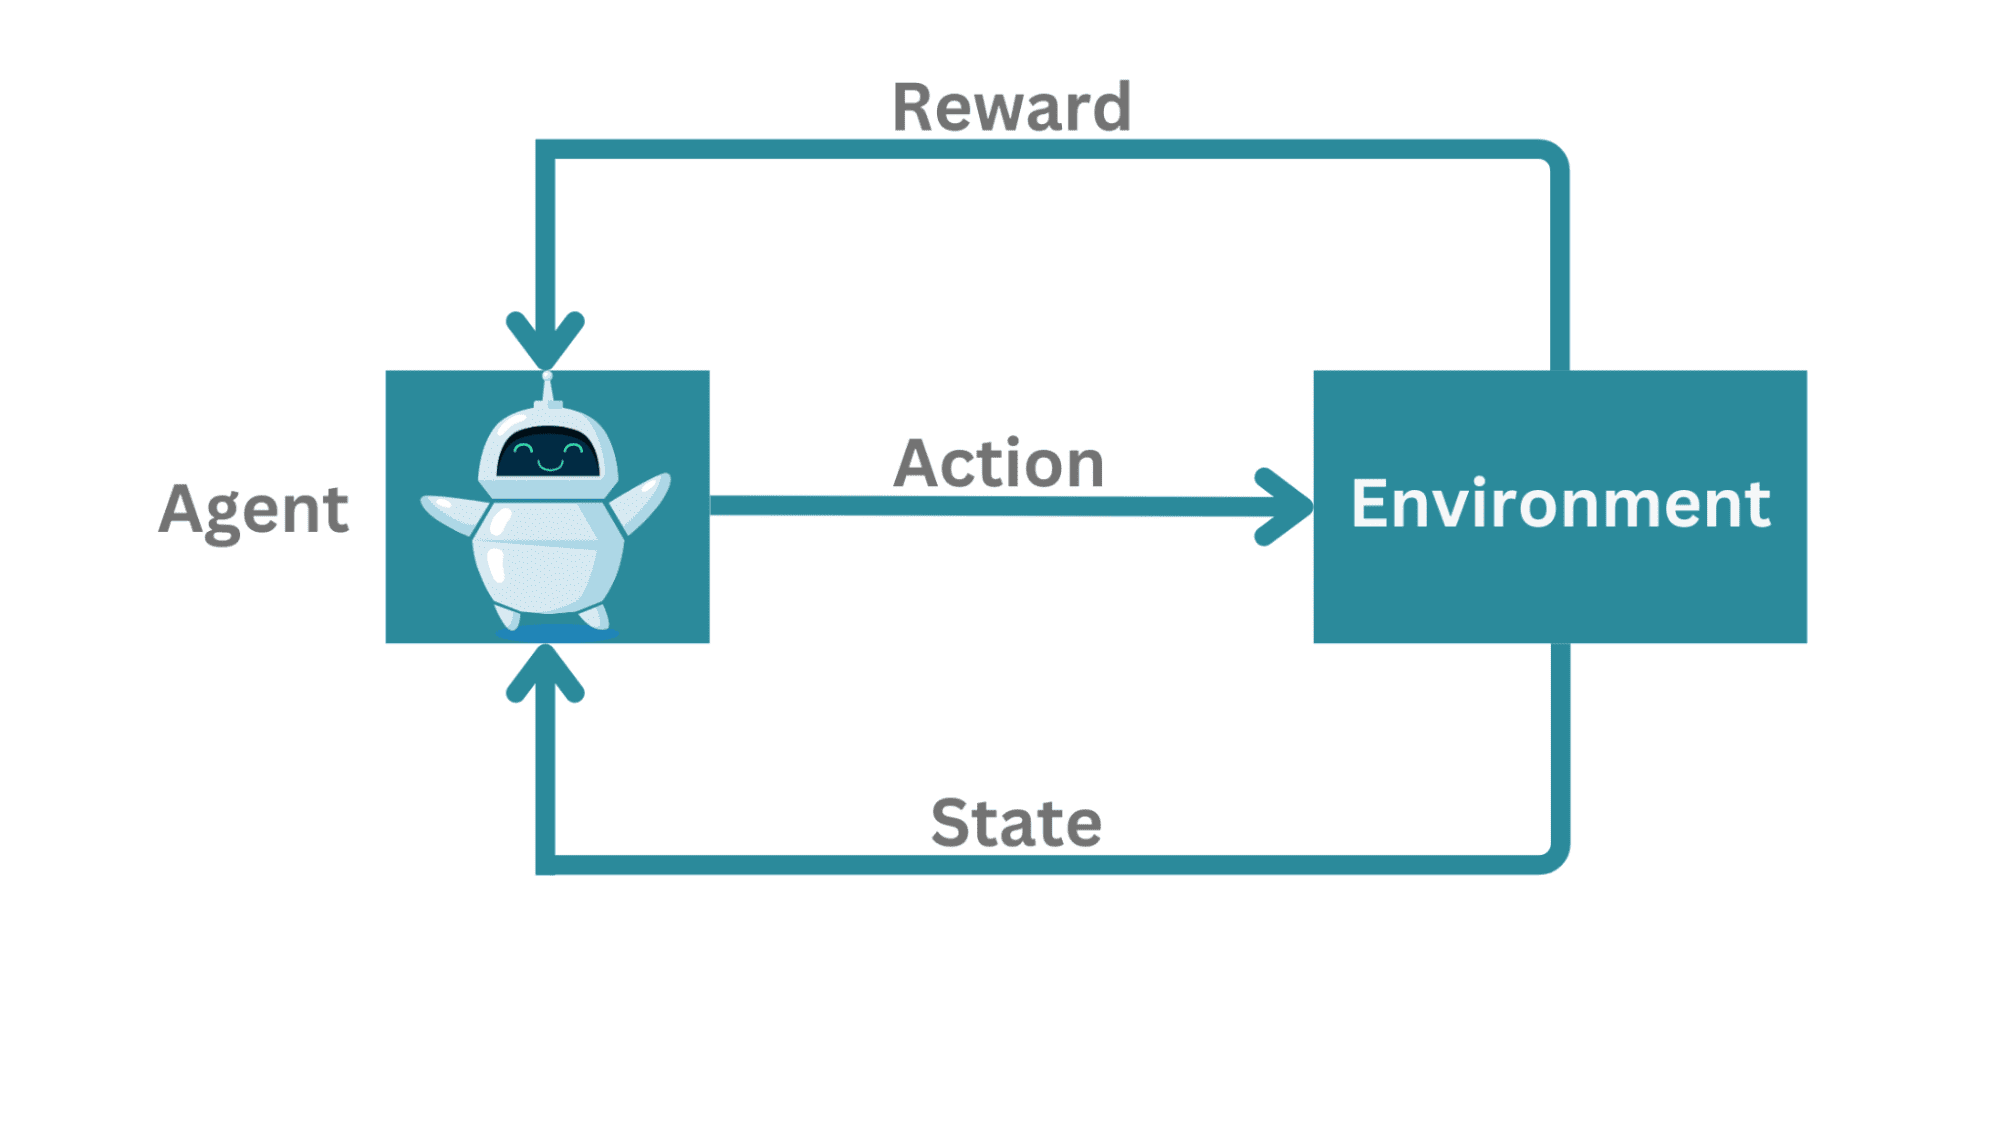
Reinforcement Learning Framework | Image by author
A typical reinforcement learning framework looks like this:
- there is Agent learn to interact with environment.
- agent can measure it statetook actionand sometimes reward.
A practical example of this setup: an agent can play against an opponent (such as a game of chess) or attempt to navigate a complex environment.
As a very simplistic example, consider a mouse in a maze. Here, the agent is no You’re not playing against your opponent, but rather trying to find your way out. If there are multiple paths leading to an exit, preference may be given to the shortest path out of the maze.

Mouse in maze | Stock Foto Mouse in maze Image by author
In this example, mouse that is Agent trying to navigate environment that is maze.of action This is mouse movement in the maze. If you successfully move through the maze to the exit, cheese pieces As reward.
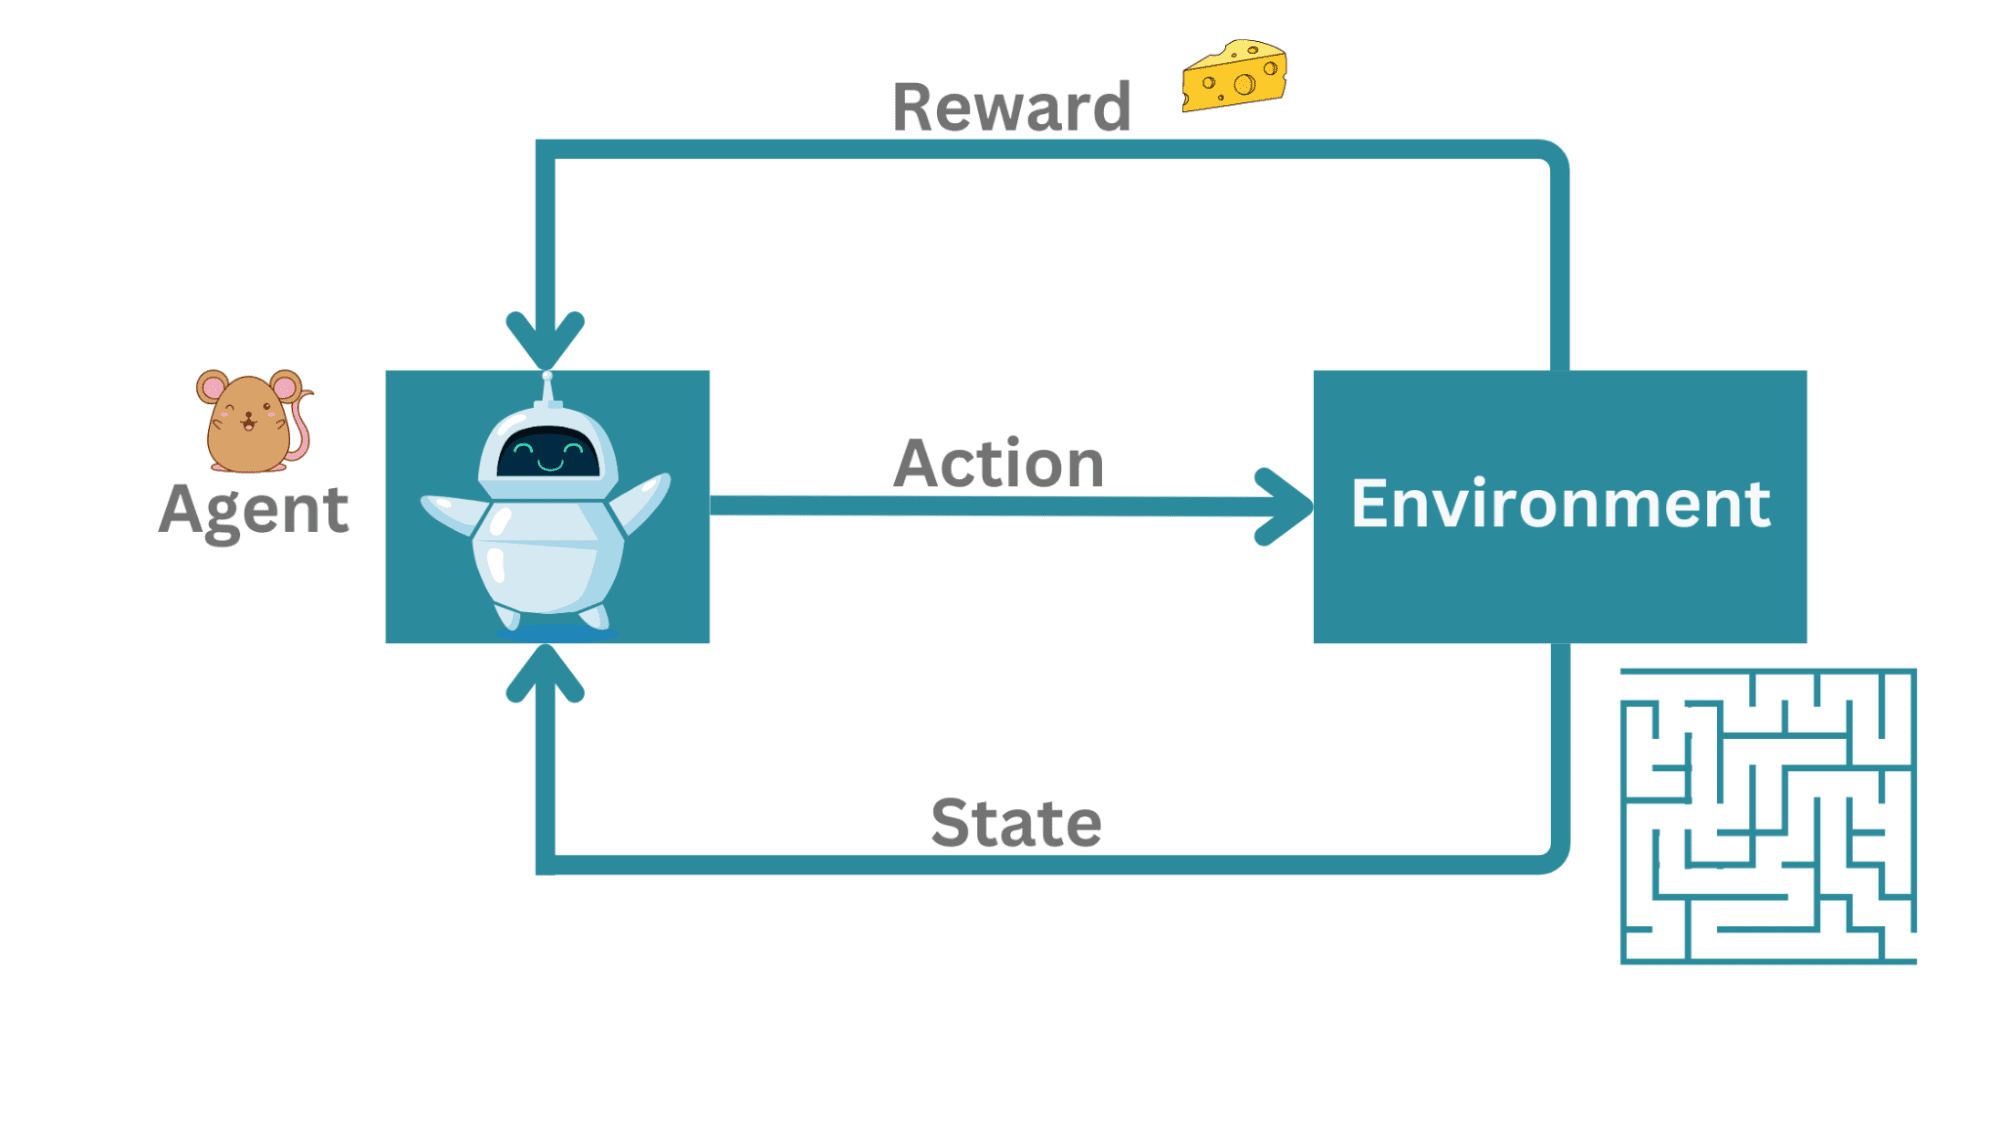
Example | Image by author
A sequence of actions occurs at discrete time steps (for example, t = 1, 2, 3, …).at any timestep t, the mouse can only measure its current state within the maze. I don’t know the whole maze yet.
So the agent (mouse) measures its state s_t in the environment at the timestep tperforms a valid action and and move to the state s_(t + 1).
Condition | Image by author
How is Reinforcement Learning Different?
Notice how the mouse (agent) has to find a way out of the maze. trial and error. Now, if the mouse hits one of the walls of the maze, it must find a way back and carve another route to the exit.
If this were a supervised learning setting, after every move the agent would know if its action was correct, leading to a reward. Supervised learning is like learning from a teacher.
Teachers will tell you in advance, but critics will always tell you how good or bad you did after the performance. For this reason, reinforcement learning is also called “learning”. presence of critics.
Terminal conditions and episodes
When the mouse reaches the exit, terminal state. That means you can’t explore any further.
A sequence of actions from the initial state to the final state is called an episode. Any learning problem requires multiple episodes for the agent to learn to navigate. Now, it would take many episodes to learn the sequence of actions that led the agent (mouse) to the exit and then received the cheese.
heavy rewards and low rewards
Each time the agent performs a correct action or series of correct actions, reward. In this case, mice receive cheese as a reward for etching a valid route through the maze (environment) to the exit.
In this example, the mouse only receives cheese at the very end, i.e. when it reaches the exit. This is an example. sparse and late rewards.
The higher the frequency of rewards, the Crowded reward system.
Looking back, we need to understand which action or series of actions rewarded the agent (which is not easy). This is commonly called the unit allocation problem.
Environments are often stochastic rather than deterministic, and so are policies.Specifying the state s_tthe agent performs an action and transitions to another state s_(t+1) with a certain probability.
A policy helps define a mapping from a set of possible states to an action. It helps answer questions such as:
- What actions should be taken to maximize the expected reward?
- Better yet, given the conditions, what is the best action the agent can take to maximize the expected reward?
So an agent can think of it like this: enact a policy π:

Another related and useful concept is value functions.of value function is given by:
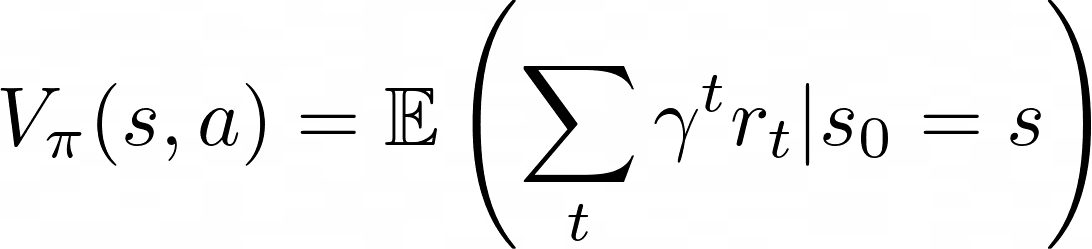
This means the value of being in a given state of policy π. The quantity indicates the future expected reward if the agent starts in state π and then executes policy π.
In summary, the goal of reinforcement learning is to optimize a policy to maximize future expected rewards. So you can think of it as an optimization problem to be solved for π.
Discount rate
Notice that there is a new quantity ɣ.What does it stand for? ɣ is called Discount rate, A quantity between 0 and 1. It means that future rewards are discounted (that is, because they are greater now than later).
Let’s go back to the mouse food loop in the maze example. If the mouse can find a route out of A with a small piece of cheese, it can be repeated to collect the cheese pieces. But what if the maze had another exit B with a bigger piece of cheese (bigger reward)?
as long as the mouse keeps moving exploit This current strategy explore The new strategy doesn’t give as big a reward as eating a big piece of cheese at Exit B.
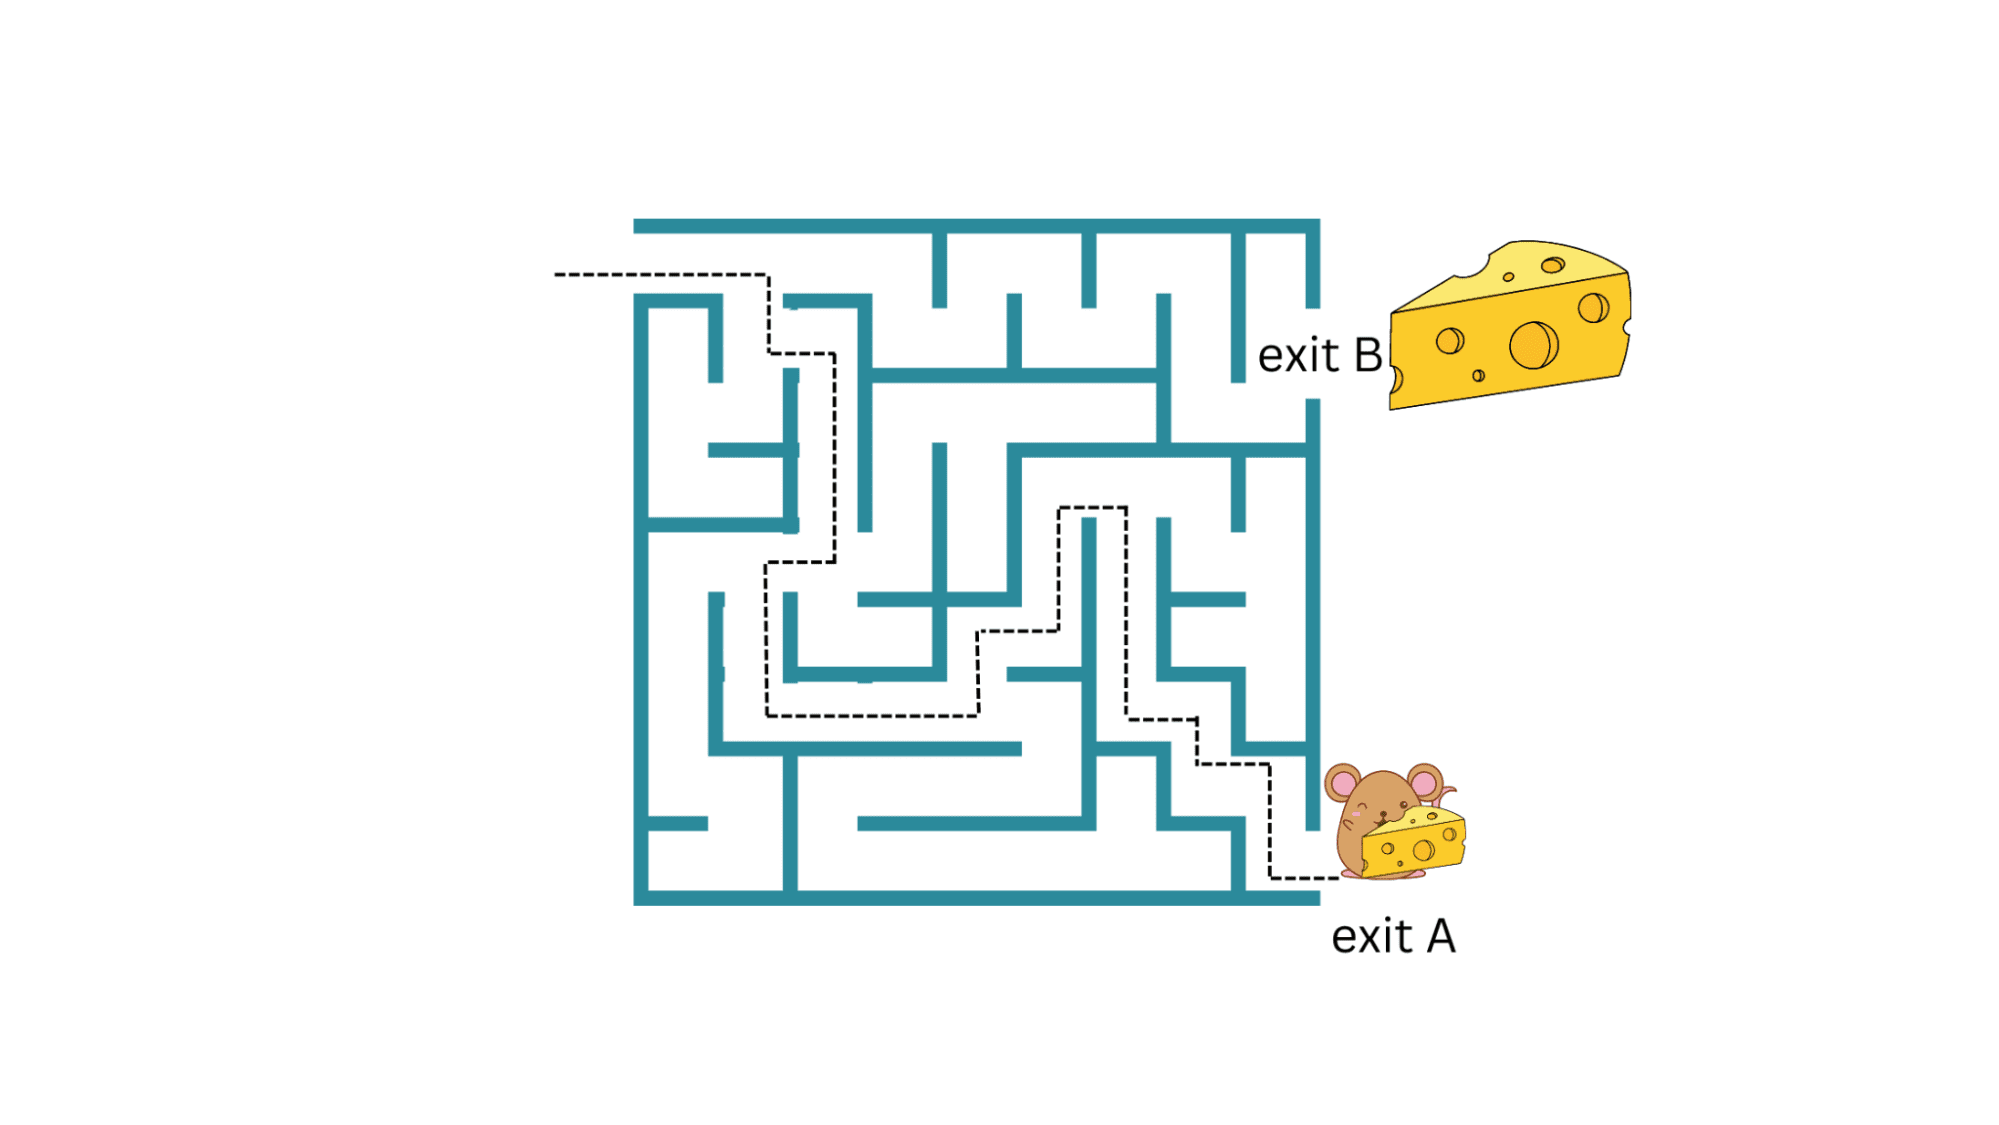
Exploration vs. Exploitation | Image by author
but uncertainty Related to exploring new strategies, future rewards are greater. So how do we leverage and explore? This trade-off between leveraging current strategies and exploring new strategies with potentially better rewards is Exploration vs Exploitation Tradeoff.
One possible approach is ε – greedy search. Given a set of all possible actions, ε – greedy search Explore one of the possible actions using probabilities ε While leveraging the current strategy with probability 1, ε.
Let’s summarize what we’ve discussed so far. You’ve learned about the components of the reinforcement learning framework.
- Agents interact with the environment, measure its current state, perform actions, and receive rewards as positive reinforcement. The framework is probabilistic.
- We then considered value functions and policies and how the optimization problem boils down to finding the optimal policy that maximizes the future expected reward.
You’ve learned enough material to navigate the world of reinforcement learning. Where do you go from here? We didn’t cover reinforcement learning algorithms in this guide, so you can explore some basic algorithms.
- However, in most cases it may not be possible to perfectly model the environment. In this case, we can consider model-free algorithms such as Q-learning that optimize state-action pairs.
If you want to learn more about reinforcement learning, David Silver’s Reinforcement Learning lectures on YouTube and Hugging Face’s Deep Reinforcement Learning Course are good resources to reference.
Bala Priya C I am a developer and technical writer from India. She likes working at the intersection of math, programming, data she science, and content creation. Her interests and areas of expertise include DevOps, Data Science, and Natural Language Processing. She likes reading, writing, coding and coffee. Now she’s working on creating tutorials, her how-to guides, opinion articles, and more to learn and share her knowledge with the developer community.