

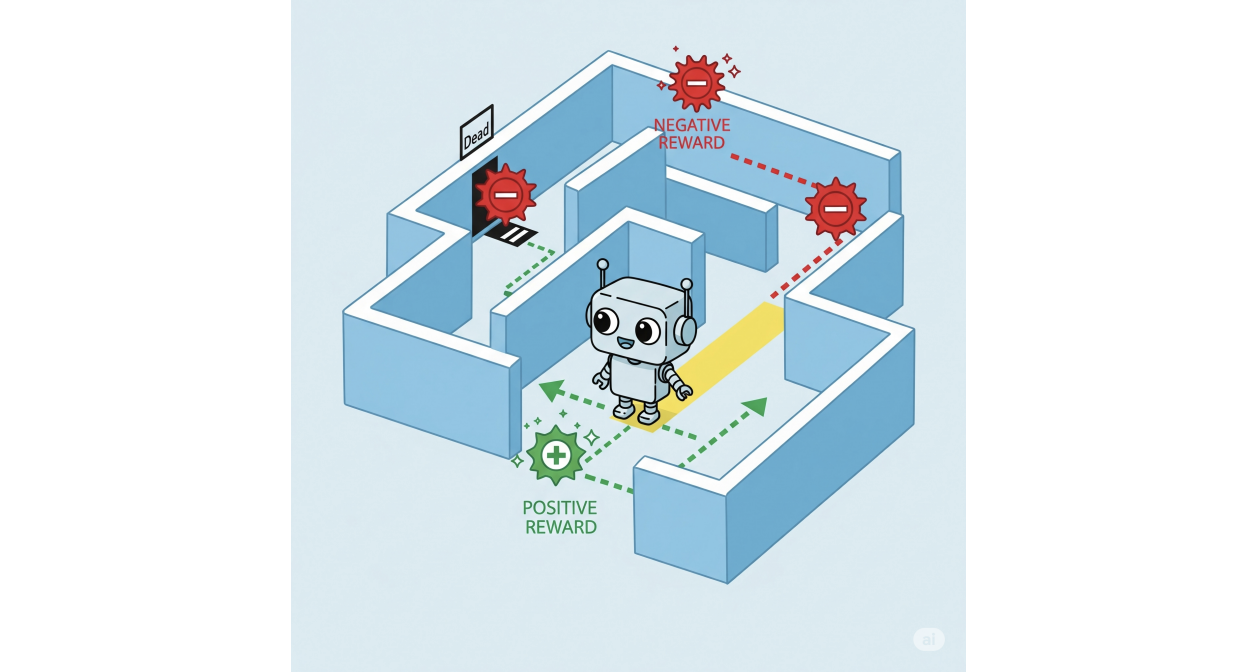
 Images provided by the author – generated using Gemini.
For many of us, artificial intelligence (AI) has become a part of everyday life, and the speed at which human roles are assigned to AI systems before shows no sign of slowing down. AI systems are key components of many technologies, ranging from increasingly to more domains, including self-driving cars, smart urban planning, digital assistants and more. At the heart of many of these technologies is autonomous agents. This is a system designed to act on behalf of humans and make decisions without direct supervision. To act effectively in the real world, these agents must be able to perform a wide range of tasks despite perhaps unpredictable environmental conditions. Machine Learning (ML) To achieve adaptive behavior.
Reinforcement learning (RL) [6] It stands out as a powerful ML technique for training agents to achieve optimal behavior in a stochastic environment. RL agents learn by interacting with the environment. Over time, they learn to maximize the expected rewards throughout the runtime.
Images provided by the author – generated using Gemini.
RL agents can master a wide variety of complex tasks, from acquiring video games to controlling cyberphysical systems such as self-driving cars, and often outweigh what experts can do. However, this optimal and efficient behavior can turn out to be unconstrained completely unconstrained, or even dangerous to the collision's people. This motivates substantial research efforts. Safe RL,Specialized techniques have been developed to ensure that RL agents meet specific safety requirements. These requirements are often expressed in formal languages such as linear temporal logic. (LTL)extends classic (true/false) logic using the time operator, allowing you to specify conditions such as “things that must always be held” or “things that must occur at the end.” By combining ML adaptability with logic accuracy, researchers have developed powerful methods for training agents to act effectively and safely.
However, safety is not everything. In fact, new challenges arise as RL-based agents are increasingly given the role of exchanging or interacting closely with humans. Social, legal and ethical norms Its structural human society often goes beyond simple constraints that guarantee safety. For example, self-driving cars may fully comply with safety constraints (e.g. avoid collisions), but are technically safe, but violate social norms and appear strange or rude on the road.
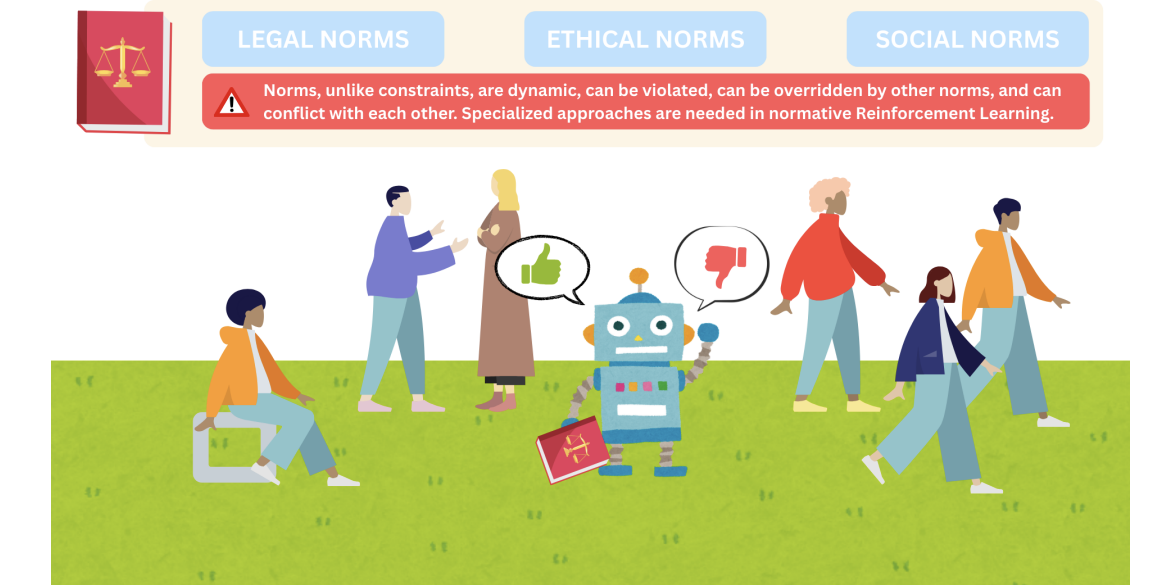
Norms are usually described as obligations (“You must do it”), permissions (“You are permitted to do it”), and prohibition (“You are prohibited from doing it”). Instead, they are the concept of deontics. They explain ideal or acceptable behavior – ideal or acceptable behavior, rather than what actually applies. This nuance introduces some difficult dynamics in reasoning about norms that many logic (such as LTL) struggle to handle. Even daily normative systems such as driving regulations can be characterized by such complications. While some norms can be very simple (for example, they will not exceed 50 kph within city limits), others can be more complicated as follows:
- Always maintain 10 meters between your vehicle and your front and rear vehicles.
- If there is less than 10 meters between you and the vehicle behind you, you Slow down To put more space between yourself and the car in front of you.
(2) is an example The opposite obligation (CTD), obligations that must be specifically followed in another situation The main Obligation (1) has already been breached, for example, to compensate or mitigate damages. Although extensively studied in the field of normative reasoning and extreme logic, such norms can be problematic for many basic secure RL methods based on the enforcement of LTL constraints. [4].
But there teeth A safe RL approach that shows more possibilities. One of the most notable examples is Restraint bolt Technology introduced by De Giacomo et al. [2]. Named after the devices used in the Star Wars universe, this method can affect the agent's actions and pursue goals to align with the specified rules. In other words, the suppression bolt modifies the behavior that the RL agent learns, and respects the set of specifications. These specifications are expressed as LTL (LTLF) variants [3]), each paired with its own rewards. The central idea is simple, but powerful. Add rewards for each corresponding specification, along with the rewards that an agent receives when exploring the environment, and for every time they meet that corresponding specification, that action is fine-tuned to work to suit their individual safety requirements. Assigning specific rewards to individual specifications allows for modeling more complex dynamics, such as, for example, CTD obligations.
Still, the problem with modeling norms persists. For example, many (if not most) norms are conditional. Consider the obligation to state that “if a pedestrian is at a pedestrian intersection, nearby vehicles must stop.” If an agent is rewarded every time this rule is met, they will receive rewards even in situations where the standard is not actually valid. This is because logic also brings implications when the precedent (“the pedestrian exists”) is incorrect. As a result, agents may be rewarded whenever there are no pedestrians around and may learn to extend the runtime to accumulate these rewards of doing nothing effectively rather than efficiently pursuing the intended task (for example, reaching the destination). in [5] We showed that no matter which reward the agent chooses, there is a scenario in which the agent will ignore norms or learn this “procrastination” behavior. As a result, I introduced it Normative suppression bolt (NRB), a step towards implementing the norms of RL agents. Unlike the original restraint bolt, which promoted compliance by providing additional rewards, the norm version punishes the standard violation. This design is inspired by Anderson View of Deontic Logic [1]treats obligations as rules that inevitably cause sanctions. Therefore, this framework does not rely on reinforcement of acceptable behavior, but implements the norms by ensuring that violations carry tangible penalties. While NRBs are effective in managing complex normative dynamics such as conditional obligations, reverse obligations, opposition to obligations, and exceptions, NRBs rely on trial and error reward adjustments to implement normal compliance, they can be cumbersome, especially when trying to resolve conflicts between norms. Additionally, they require retraining to accommodate norm updates and do not lend to ensure that optimal policies minimize norm violations.
Our contribution
I'll introduce it when I build it on NRBS Ordered normative constraint bolts (ONRB), a framework for guiding reinforcement learning agents to comply with social, legal and ethical norms while addressing the limitations of the NRB. In this approach, each norm is treated as the objective of a multi-objective reinforcement learning (MORL) problem. By reformulating the problem in this way, you can:
- If norms are consistent, we prove that agents who learn optimal behavior minimize norm violations over time.
- It expresses relationships between norms from the perspective of a ranking system that explains the norms to prioritize when conflicts occur.
- Using MORL techniques, we algorithmically determine the required magnitude of the punishment we assign, and As long as the agent learns optimal behavior, the criteria are breached as much as possible, ensuring that the highest norms are prioritized.
- Respond to changes in the norm system by “deactivating” or “reactivating” certain norms.
We tested the framework in a grid world environment inspired by a strategy game. Agents have learned to collect resources and distribute them to designated areas. This setup allows us to demonstrate the ability of the framework to handle the complex normative scenarios mentioned above, along with direct prioritization of competing norms and norm updates. For example, the following diagram
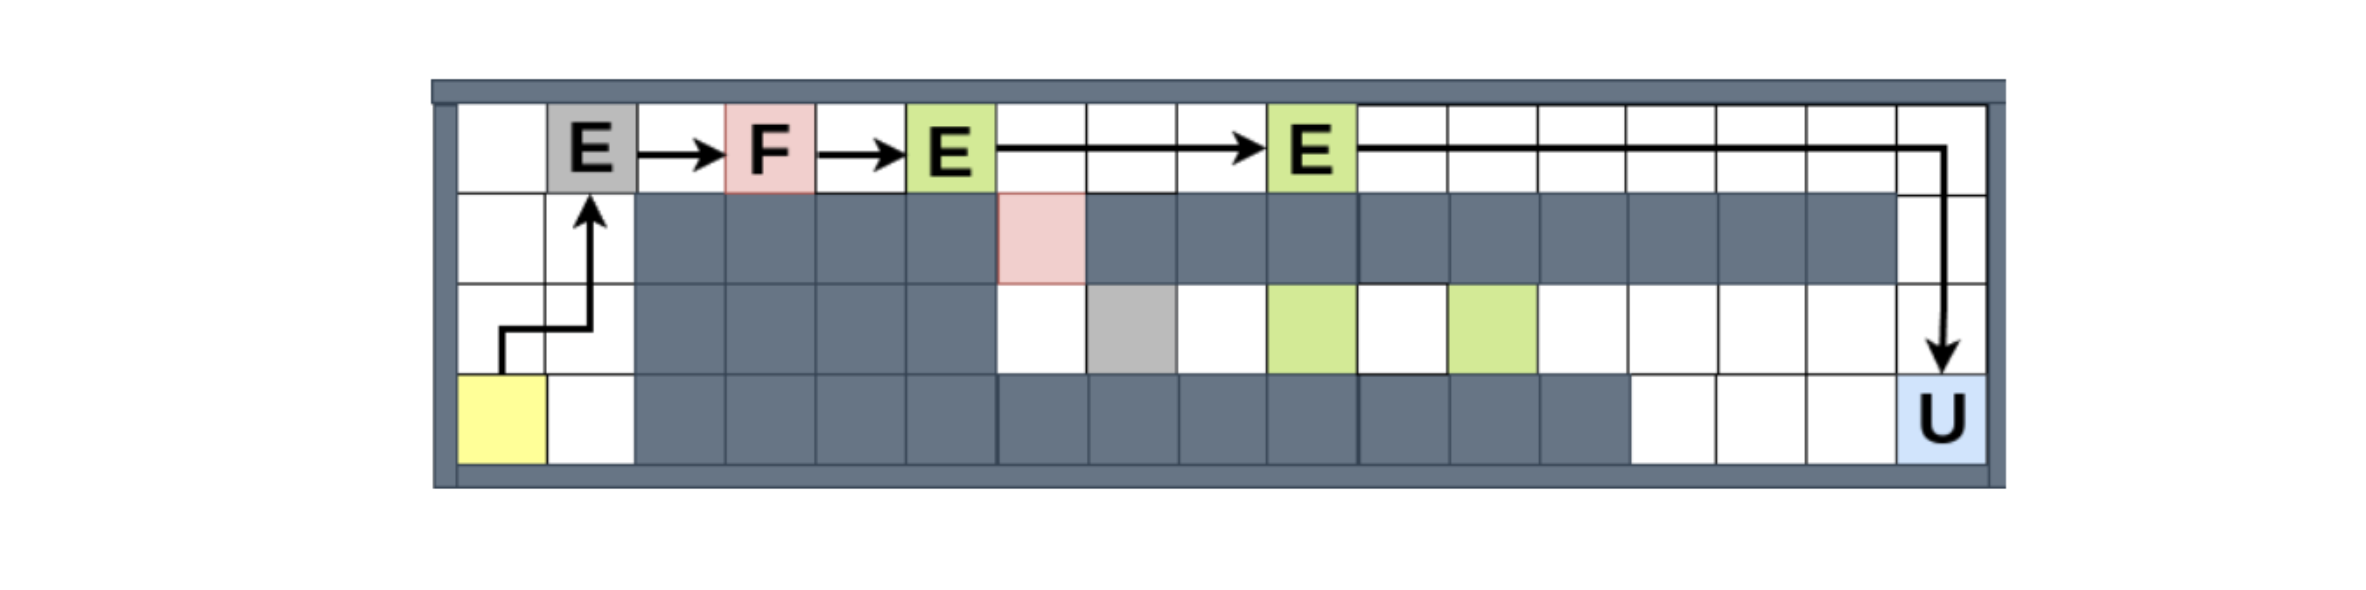
Shows how the agent handles normal conflicts. Assume (1) avoid dangerous (pink) areas and (2) certain deadlines reach the market (blue) area, with the second standard taking precedence. (1) You will see that you choose to violate. Otherwise, it's because you'll be stuck at the top of the map and can't meet (2). Nevertheless, (1) choose a compliant path even if you are given the possibility of violating again, even if you can collect more resources on the path you are violating and therefore more rewards from your environment.
In summary, combining RL and logic allows you to build an AI agent that not only works but also works correctly.
This work won Distinguished Paper Award at IJCAI 2025. Read the paper in full: Learn normative behavior by combining MORL with suppression bolts, Emery A. Neufeld, Agatasiabatoni, and Radhuflorinturkan.
Acknowledgments
This study was funded by the two-sided AI cluster of the Vienna Science and Technology Fund (WWTF) project ICT22-023 and the Austrian Science Fund (FWF) 10.55776/COE12 Excellence.
reference
[1] Alan Ross Anderson. Desorting and removing modal logic and reducing logic. heart67 (265): 100–103, 1958.
[2] Giuseppe de Giacomo, Luca Iocchi, Marco Faveito, and Fabio Patrizi. Basics of suppression bolts: Reinforcement learning with LTLF/LDLF suppression specifications. in Proceedings of the International Conference on Automatic Planning and SchedulingVolume 29, pages 128-136, 2019.
[3] Giuseppe de Giacomo and Moshe y Vardi. Linear time logic and linear dynamic logic on finite traces. in ijcaiVolume 13, pages 854-860, 2013.
[4] Emery Neufeld, Ezio Bartocci, Agata Ciabattoni. About normative reinforcement learning through safe reinforcement learning. in Prima 2022, 2022.
[5] Emery A Neufeld, Agata Ciabattoni, Radu Florin Tulcan. Normative compliance of reinforcement learning agents via inhibitory bolts. in Legal Knowledge and Information Systems Julix 2024pages 119-130. iOS Press, 2024.
[6] Richard S. Sutton and Andrew G. Barth. Reinforcement Learning – Introduction. Adaptive calculations and machine learning. MIT Press, 1998.
Agata Ciabattoni is a professor at Tu Wien.
Emery Neufeld is a postdoctoral researcher at Tu Wien.


