AI has been able to solve extremely difficult problems in the field of mathematics, yet it still struggles to automate a large number of fundamental tasks.
In the view of Diogo Almeida, founder and CEO of US AI startup TypeSafe, the problem may not be that AI is “not smart enough”, but that past models were not designed for the real software world from the very beginning.
Jev is the answer he put forward. It is the first large programmable model released by TypeSafe, defined as a “System One Model”. It is not chat-centric, nor does it take benchmark scores as its main goal. Instead, it attempts to make the model directly part of the software. Its only core optimized metric is intelligence per dollar.
After the release of Jev, its name was everywhere on social media, 100,000 people flooded into the Discord community overnight, and the total views of its release videos exceeded 38 million.
Almeida previously participated in the construction of OpenAI’s instruction-following models. After leaving OpenAI, he spent more than two years searching for the answer to another question: why an AI that is already smart enough still finds it difficult to reliably integrate into real workflows.
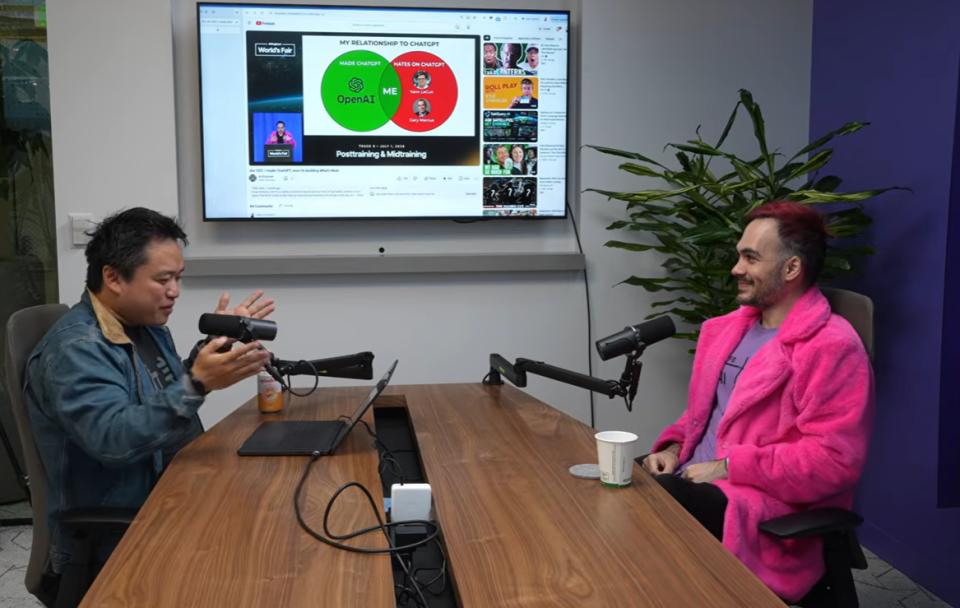
A few days after Jev was launched, he gave an exclusive interview with tech podcast host swyx.
Throughout the interview, Almeida repeatedly emphasized several points:
First, the biggest gap for AI right now may not be capability, but reliability. Models can answer complex questions, but when they actually enter the software backend, occasional refusal to respond, output drift or unpredictable behavior may cause the entire system to fail.
Second, TypeSafe does not want to make AI a chatbot that is “more human-like”, but to turn it into intelligent infrastructure that software can call directly. In Almeida’s view, AI should be more like a database than a colleague.
Third, RLCD (Reinforcement Learning from Code Feedback) represents TypeSafe’s redefinition of the model training direction. RLHF (Reinforcement Learning from Human Feedback) optimizes for “what humans like”, RLVR (Reinforcement Learning from Verifiable Reward) focuses more on verifiable tasks, while the goal of RLCD is to enable the model to work reliably in the program loop.
Fourth, reliability does not equal determinism. Getting exactly the same output for the same input forever is not necessarily the most important thing. For real software, what matters more is that similar problems can get similar results.
Fifth, future software may no longer call AI as a single large model, but split tasks into a large number of smaller, easier-to-verify intelligent decisions. States, instructions and standards can all be structured, and the model will be placed in the position where software truly needs intelligence.
Almeida even believes that if he was only given 1 billion US dollars, he would not choose to pre-train a large model from scratch. He would prefer to invest resources in data, post-training and new forms of intelligence.
The following is the condensed version of the interview transcript:
01 The “System One Model” Built for Code
Q: Why did you start building TypeSafe and Jev?
Almeida: I’ve been thinking about one question: Why can AI already solve Millennium Prize Problems in mathematics, but still can’t automate many basic tasks? I later realized that what is missing may not be a more powerful automation engine, but the “plug” that connects AI to real economic work.
When I was working on instruction-following models at OpenAI, I found that although the models are good at “input instruction, output text”, a lot of value ultimately stays in scenarios such as copy generation. So I started thinking: if AI is to become infrastructure, who will the real consumers be? My answer is code. That’s why we built Jev later.
Q: For those who don’t know it, define Jev in one sentence. What is Jev?
Almeida: Jev can be defined as “machine-native, system-one, large-scale, programmable model”, with the core goal of making code the direct consumer of the model.
The so-called System One Model refers to a fast, direct and reliable model that makes small decisions in programs, and its output can be directly consumed by code. The System Two Model is a slow model with long reasoning chains, good at mathematics and complex reasoning, but fragile, uneven and expensive. Diogo’s core point is that the industry has paid excessive attention to System Two reasoning models, but it is System One that can automate work that generates economic value.
Different from pre-trained models for Internet text completion and RLHF models that mainly focus on instruction following, Jev is designed around program usage from the very beginning, and is optimized for software from the inside of the model to the external interfaces. The metric we really care about is “intelligence per dollar”. Cost and speed certainly matter, but what end users pay for is ultimately intelligence.
Jev aims to be at the cutting edge of this metric. We believe that for a truly good model, once users start using it, they will soon feel whether it is really useful.
02 The Poison of RLHF: How Mode Collapse Undermines Calibration
Q: You have been criticizing RLHF. What is its biggest problem?
Almeida: I think the biggest problem is that it tends to make the model too conservative, which is the so-called “mode collapse”. In order to avoid making mistakes as much as possible, the model will gradually abandon rare but potentially valuable answers, and only choose the safest results that are most likely to get rewards. In this way, the model seems to be more stable, but in fact it loses a lot of exploration space.
Q: How does this relate to Yann LeCun’s point of view?
Almeida: I trust Yann LeCun very much, and many of his views are very accurate. He has a famous diagram showing that the longer the content generated by a language model, the higher the probability of errors. But I think the actual situation is not that simple. In order to avoid mistakes, the model will become more and more confident or more and more conservative, and eventually compress its own judgment space. That’s why I think it’s not a good solution to directly use models that are mainly used for text generation to make complex decisions.
03 RLCD: Removing Humans from the Loop
Q: What is RLCD? What is the difference between it, RLHF and RLVR?
Almeida: RLCD is not a term created just to sound cool. It represents our new “North Star”. The goal of RLHF is to make the model better understand human instructions and give answers that humans like. RLVR is more used for tasks that can be automatically verified by programs. RLCD enables the model to work reliably in the program loop. In the past, “humans are in the loop”, and programs are only auxiliary tools. We hope to move humans out of the loop and let programs truly enter the loop.
Q: You position TypeSafe as a data lab rather than a model lab?
Almeida: We have always attached great importance to data. Model capabilities are ultimately inseparable from data, and data itself is incredibly complex. Reliability also comes from data. Richard Sutton, the 2024 Turing Award winner, once said that roughly speaking, algorithms will eventually outperform computing. I believe even more that data is more important than computing. The real difficulty is to choose the right tasks and find the right direction.
If we look back at the development of LLMs, I think there have been several important directional changes: RLHF, RLVR, and now it’s the turn of the RLCD we proposed. We will not train models on user data, because real-world data has a lot of bias and distribution problems. We care more about what AI will look like years from now. Our goal is to make the model a general-purpose infrastructure that goes deep into places in the software stack that are unimaginable today.
Q: Why is data so important?
Almeida: It’s hard to imagine how much data can change things in advance. Our data team has been studying the core capabilities of the model. They will find out where the model performs unstably, and then deal with these problems little by little. It’s not just about solving a specific case, but finding the general rule behind it. This requires a lot of intelligence, so we have been recruiting talents in the data field.
Q: If you were given 1 billion US dollars right now, how would you invest it? Would you train a large model from scratch?
Almeida: No. If I only had 1 billion US dollars, I would not choose to pre-train a large model from scratch. I would invest more resources in data, post-training, and new forms of intelligence.
Training a foundation model from scratch today requires huge computing resources, and many companies are doing similar things. What I am more interested in is continuing to explore what else the model can become on the existing basis, and how to make intelligence truly enter software and real workflows through data and training methods.
That’s why we put a lot of energy into data and post-training. What really matters is not simply making the model larger, but finding new ways to make the model more useful and more reliable.
04 Not Chasing Public Benchmarks, and Not Relying on Refusal to Guarantee Safety
Q: Why do you oppose public benchmarks?
Almeida: Because public benchmarks are very easy to be “gamed”. Even if the people who set the questions try to avoid it, model developers can still find various ways to optimize for the tests. In the past, every lab had people who specifically collected data similar to MMLU to make the model look stronger on a certain benchmark. Essentially, this is still preparing for exams, just with an extra layer of packaging.
I believe that in the long run, real trust comes from actual use. Put the model into a real workflow, test it with real tasks, and then feel for yourself whether it is good or not. What we really care about is continuously improving reliability, not making a public score higher.
In fact, we could have released Jev a year and a half ago, but that would mean we have to accept something we are not satisfied with. When we were raising funds, some people asked us to produce benchmark results, but we insisted that this is not the path we want to take. Once some principles are determined, they should be adhered to.
Q: You also don’t do traditional security alignment, and don’t set up refusal to respond. Why?
Almeida: I don’t oppose security principles, but I think security alignment is sometimes inconsistent with user needs. For a chatbot, refusing to answer may not be a big problem. When a person encounters a chatbot that refuses to answer, they can still continue the conversation. But if AI is a software dependency running in the background, once it suddenly refuses to execute, other programs that depend on it may directly malfunction.
But for software engineers, this is unacceptable. I think intelligence is more like a database than a colleague who needs to discuss values with you. The database will not judge whether the data it provides will be “misused”, it just provides data. If we write too many moral judgments directly into the intelligence itself, we will split the intelligence into smaller and smaller pieces. Every additional layer of restrictions for specific scenarios may cause the model to lose part of its general capabilities.
Q: There are three primitives in Jev’s API: choice, score, and no. How did these concepts come about?
Almeida: We discussed these concepts for a very long time. “no” comes from Bernoulli probability, which can be understood as a continuous “yes or no”. We even thought about calling it “pool party”, but no one agreed. These concepts are deliberately not directly mapped to the types in traditional programming. For example, score is not an ordinary integer, and no is not a simple Boolean value. They are very close to traditional types, but not exactly the same. We focus more on clarifying what the model can actually do, rather than making it look like something developers are already familiar with.
ba b
Q: How do they correspond to programming concepts specifically?
Almeida: choice is closest to the switch in the program, which can be understood as selecting one from several options; no corresponds to the if judgment; score is closer to sorting or setting a threshold. This has always been our vision: there will be more such types in the future, all of which can directly correspond to a certain programming primitive.
The same goes for inputs. States, instructions, and judgment criteria can all be passed to the model as structured JSON objects, and the program decides where to place them, instead of stuffing all of them into a template. If you still rely heavily on templates and system messages, you are still thinking about AI in the old way.
05 How to Use Jev: Split Problems into Small Enough Pieces
Q: How should developers use Jev? Do you have any specific suggestions?
Almeida: Split problems into the smallest semantic units. Instead of asking a very complex question at once, ask many independent small questions so that each question is easy to evaluate.
System messages are a bit like a huge global variable: you put all the instructions in at once, and then hope the model will remember every requirement forever. I think this approach is very strange in itself. A better way is to pass states, instructions and judgment criteria to the model as structured data, and let the program decide where they should be placed.
Q: Why not just ask everything together?
Almeida: I have done benchmark tests myself. Stuffing all the content into a system prompt and letting the model generate a large answer at once is not only slower, more expensive, and less effective than splitting the task into a hundred independent questions, but also very cumbersome. More importantly, this approach is very difficult to rely on.
I would be very disappointed if our model cannot run stably in the background. After splitting the task, you can check whether each step is executed correctly. If something goes wrong at a certain step, you can also locate it quickly. This essentially turns AI into a testable software component, rather than something that can only “remember” things by context.
Q: Can you give a specific example?
Almeida: Take refusal to respond as an example. You can directly ask the model: “Should I refuse to answer now?” This is a relatively simple question, and the model usually handles it well. But a better method is to split all kinds of situations that require refusal into many independent questions, and let the program clearly tell the model what to judge.
If you find that the model does not handle a certain situation correctly, add this situation separately, set a threshold, and save it as a test case. Every time you update the model later, you can retest it. In this way, the software will not “forget” this problem due to a context change. This is what I call “ML without ML”: you are still using machine learning, but the behavior of the entire system has become testable and verifiable.
06 Reliability and the Future of Coding Agents
Q: What exactly do you mean by reliability? Is it the same as determinism?
Almeida: Reliability is a very broad concept. As long as AI cannot automatically complete a task, there is usually some kind of reliability problem behind it. Determinism means that the same input gets the same output. I think this is useful for some unit tests, but it is not our most important goal.
We value robustness more, that is, when the input changes slightly, as long as the meaning is basically the same, the model should still give similar results. For example, we will add different UUIDs or random strings to the prompt, and then check whether the model can give similar answers to these essentially identical questions.
Determinism can bring some cost benefits, but it may sacrifice part of the intelligence. Our goal has always been to stay at the cutting edge of “intelligence per dollar”. If someone can prove that determinism is really very valuable and GPUs are no longer scarce, we can certainly consider it. But for now, it may mean paying higher costs for less intelligence.
Q: What do people mainly use Jev for after its release?
Almeida: We sorted out several types of use cases starting from first principles.
The first category is “dark data”, which refers to the massive amount of data accumulated by large companies. This data is inherently valuable, but in the past, the cost of analyzing it with LLMs was too high, so it could only be left