

After three consecutive releases at once, Google no longer held back.
Today, Google DeepMind made three major announcements simultaneously, unveiling three aces at once.
- gemini 3.6 flash
- gemini 3.5 flashlight
- Gemini 3.5 Flash Cyber
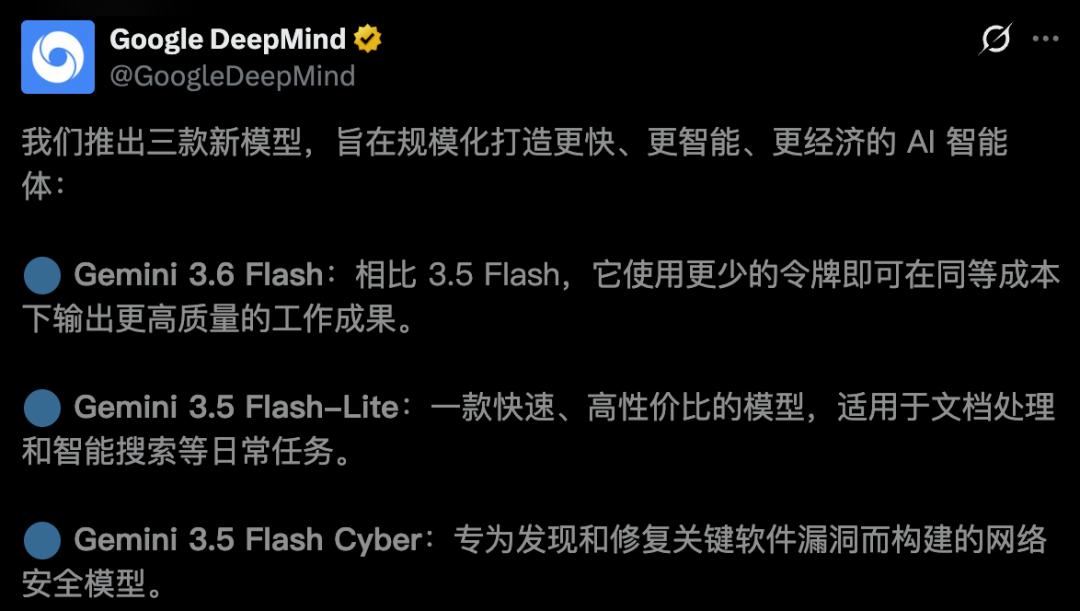
A more powerful main model, faster lightweight variants, and dedicated security specialists built specifically for vulnerability remediation.
These three Gemini models demonstrate the same goal of making AI agents running in production faster, smarter, and more affordable.
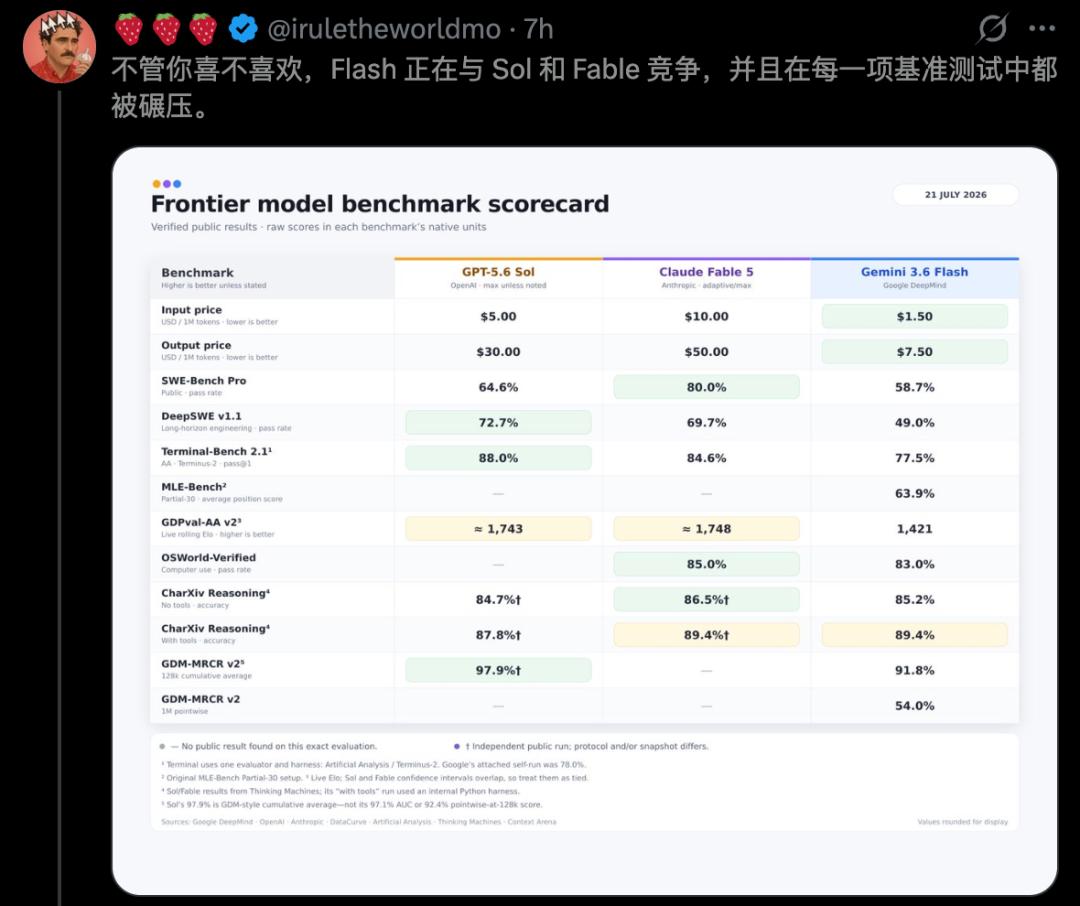
And on the very same release day, Google also dropped an even bigger bombshell.
Google DeepMind has “launched its most aggressive pre-training campaign ever” targeting its next generation model Gemini 4.
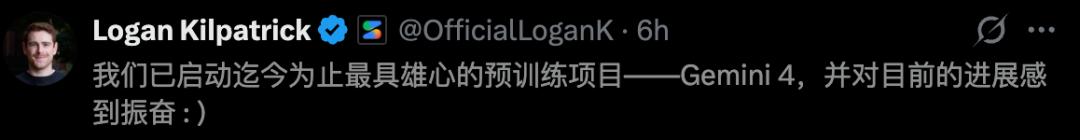
On the one hand, three new Gemini models are released in quick succession. On the one hand, Gemini 4’s development is already in full swing.
The signals Google is sending couldn’t be clearer. In this ultimate high-stakes game of AI, the real fight is just beginning.
Google’s big late night announcement
Three Gemini models presented together
Let’s analyze these three Gemini models one by one.
Gemini 3.6 Flash: 65% reduction in token consumption
First, let’s take a look at the real “highlighter” of this announcement: Gemini 3.6 Flash.
Its main highlight is the significant reduction in token usage.
As measured by the Artificial Analysis Index, it uses 17% fewer output tokens compared to the previous generation 3.5 Flash.
Coding benchmarks like DeepSWE can save you up to 65% of your tokens.
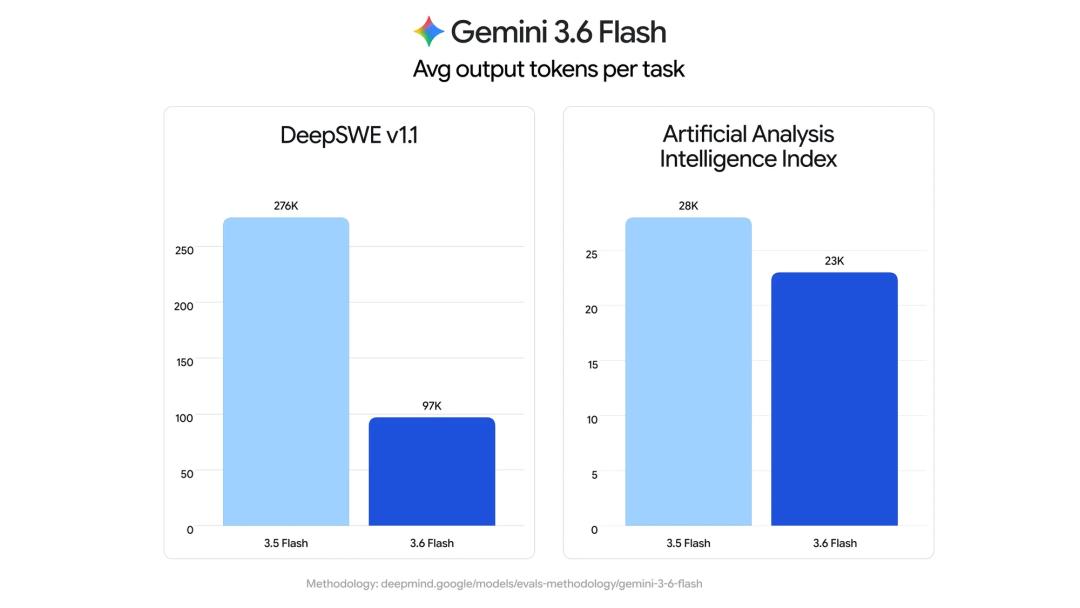
Not only does it generate less unnecessary output, it also reduces the inference steps and tool calls required to complete multi-step tasks, reducing detours and resulting in increased speed and reduced costs.
In addition to that, Gemini 3.6 Flash reduces the consumption of tokens, but its price is further reduced.
At $1.5 per million input tokens and $7.5 per million output tokens, it is cheaper than 3.5 Flash.
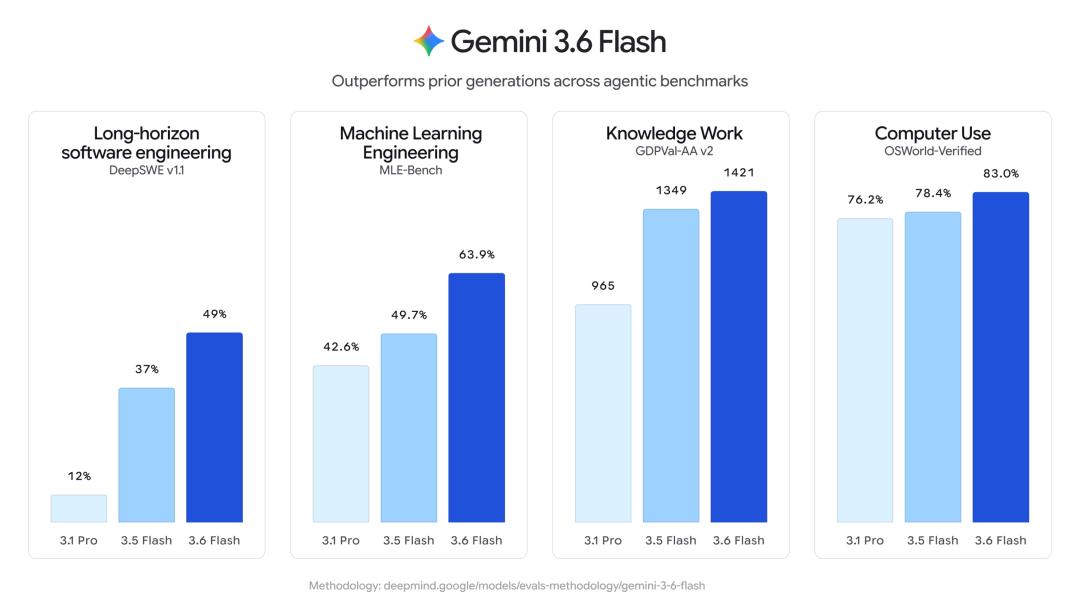
Increase efficiency, reduce costs, improve performance – that’s true integrity. 3.6 Flash outperforms previous products across multiple key benchmarks —
- DeepSWE: Programming test performance increased from 37% to 49%
- MLE Bench: Machine learning research test performance increased from 49.7% to 63.9%
- OSWorld Verified: Direct computer test performance increased from 78.4% to 83%
- GDPVal-AA v2: 1,421 knowledge-intensive work tasks completed, more than 70 points improvement over previous generation
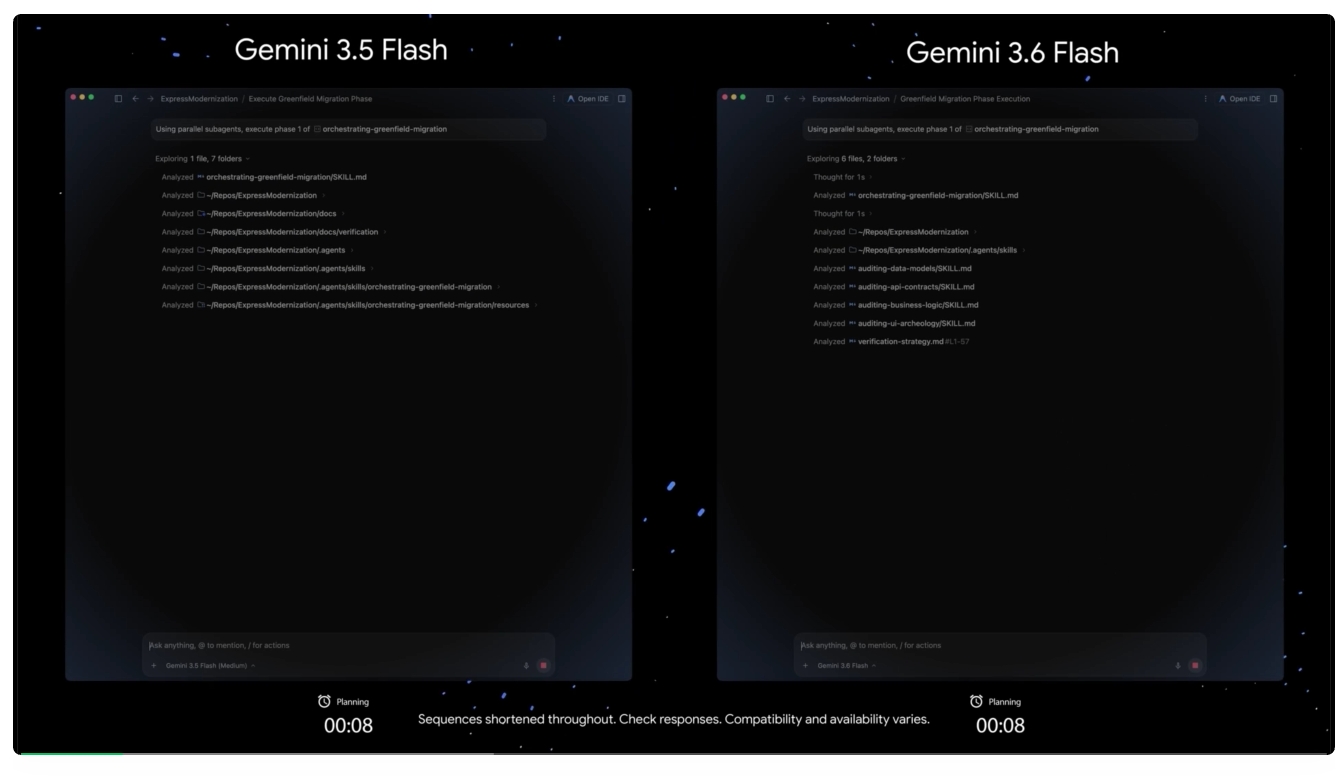
The demo below demonstrates the impressive multi-agent orchestration capabilities of 3.6 Flash. It not only handles complex code migration tasks with ease, but also provides a dimensionality reduction upgrade over 3.5 Flash in both response speed and code quality.
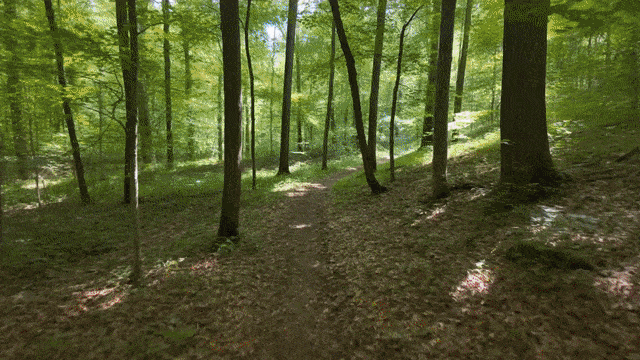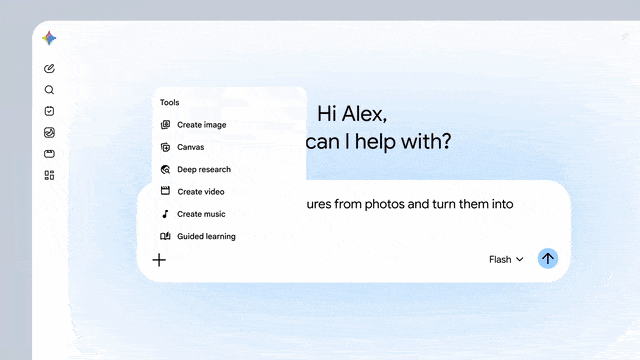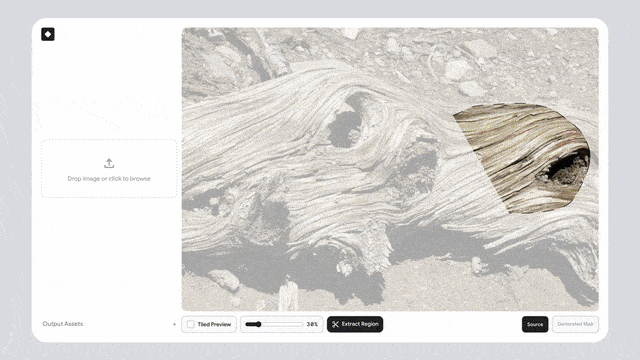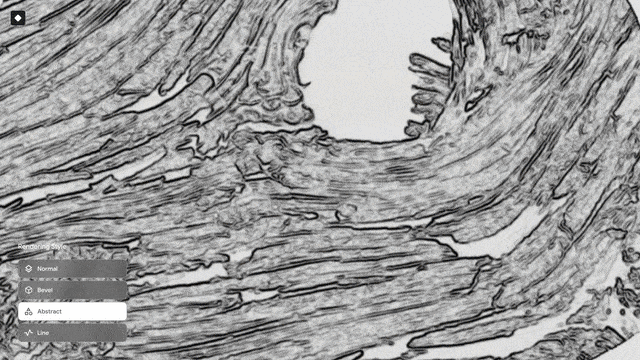
3.6 Flash with Gemini Canvas enables a complete 3D workflow, allowing users to manually build professional photo-grade texture extraction tools in minutes.
You can also transform into an “AI interaction designer” and easily create incredibly immersive theme studios.
3.5 Flash-Lite: Outperforms its older siblings
The second model, Gemini 3.5 Flash-Lite, takes a different path by prioritizing extreme speed and ultra-low cost.
3.5 Flash-Lite delivers output speeds of 350 tokens per second, the fastest in the entire 3.5 series.
Its price is surprisingly low: $0.3 per million input tokens and $2.5 per million output tokens.
Extremely fast and extremely affordable, this product is purpose-built for high-volume, high-frequency scenarios such as high-volume document processing and agent searches.
Most impressively, it outperformed its “siblings” in its product lineup.
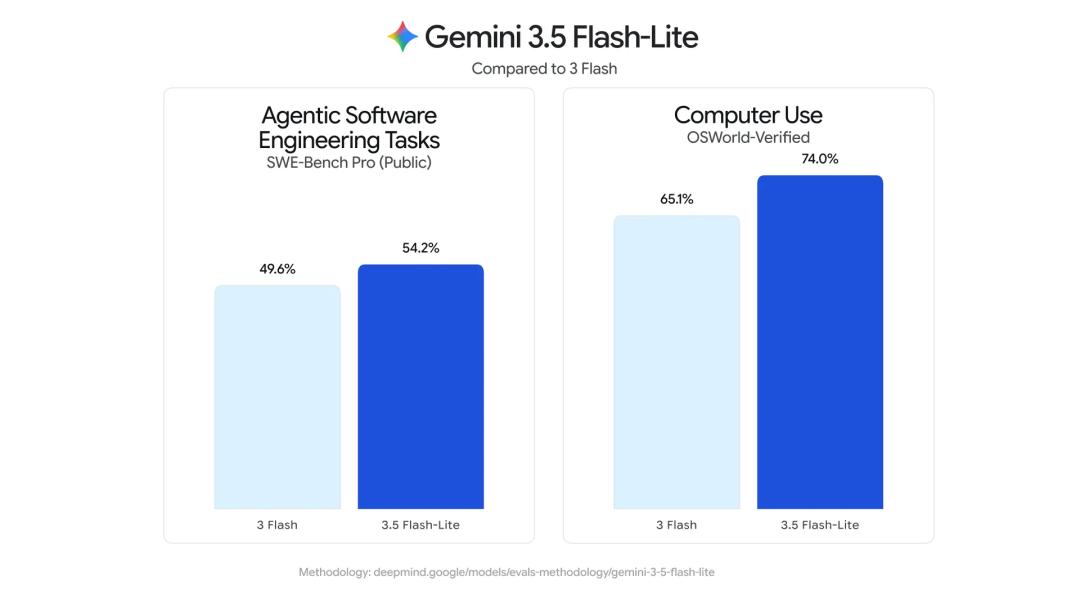
Across multiple programming and agent benchmarks, this lightweight and small model outperforms the much larger Gemini 3 flash.
- SWE-Bench Pro: 54.2% vs. 49.6%
- OSWorld Verified: 74.0% vs. 65.1%
3.6 Flash acts as a “master brain” that breaks down complex tasks, and Flash-Lite acts as a “distributed worker” that handles bulk execution.
With one model handling planning and the other handling execution, you can easily eliminate high concurrency pressure.
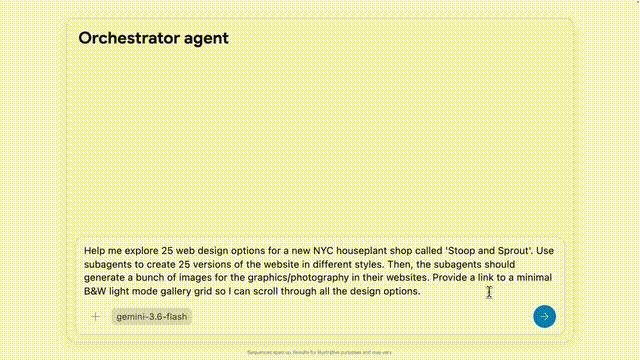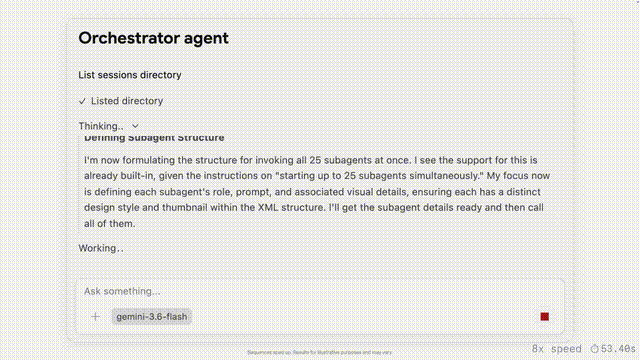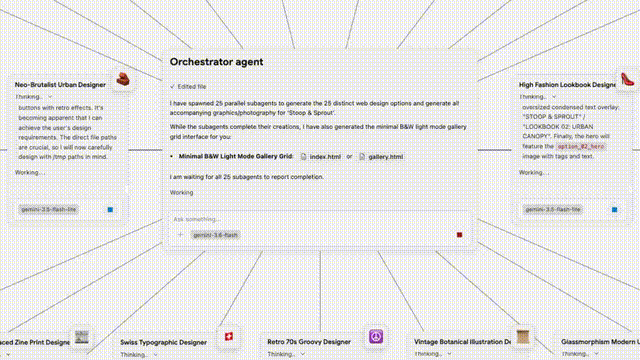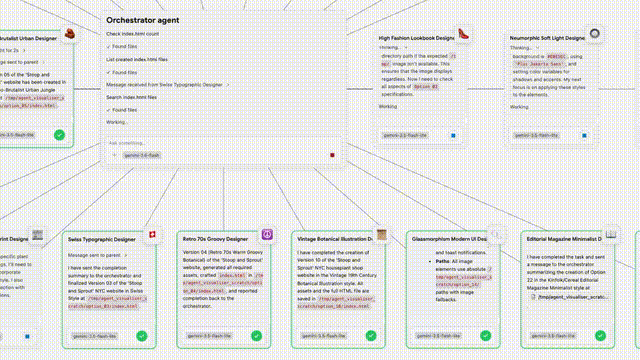
In the official demo, the two models work together. Flash-Lite generates 25 sets of highly available web design solutions at a time. It’s so fast that it feels like you can think of a task and immediately see a batch of output.
Flash-Lite is currently available in the Gemini app and will gradually roll out to Google Search.
Flash Cyber: Built for vulnerability patching, but not accessible to everyone
Gemini 3.5 Flash Cyber is a hardcore model dedicated to cybersecurity.
We have one mission: identify vulnerabilities and remediate them.
The troubling reality today is that AI can find and patch vulnerabilities faster than existing systems.
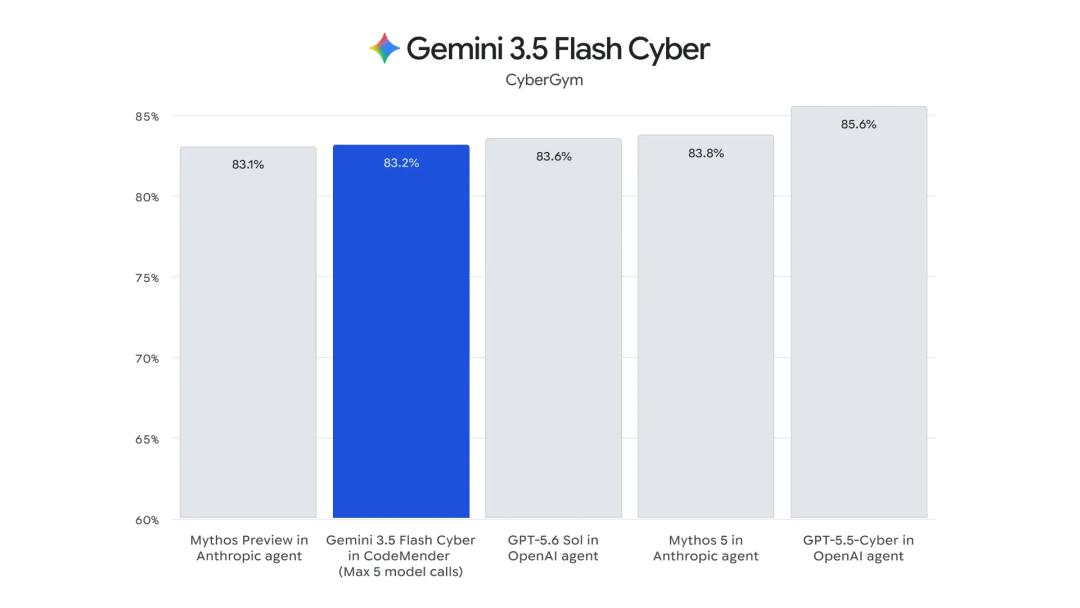
Google has integrated this model into CodeMender, a code security intelligent agent. By leveraging the coordinated operation of multiple CyberAgents, we set a new SOTA in CyberGym, a cybersecurity benchmark, at a much lower cost than larger, heavier models.
Use lighter models to handle tasks that require the highest precision.
However, this model will not be sold to the general public for the time being.
Gemini 4 development underway
The most aggressive pre-workout ever
Training for Gemini 4 has already begun even before Gemini 3.5 Pro is fully released.
These three consecutive launches are just the appetizers. The official announcement that grabbed everyone’s attention is the real main event.
Google has confirmed that it has launched its most aggressive internal pre-training campaign in its history, with the clear goal of developing Gemini 4.
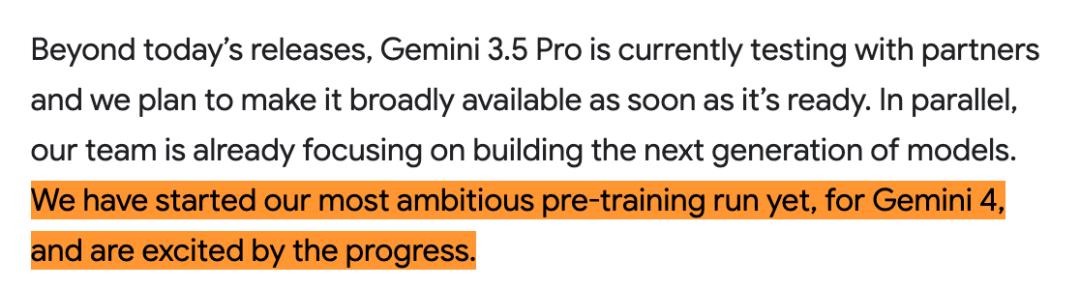
Industry experts say Gemini 4 could arrive as early as the end of this year, following Google’s typical six-month training cycle.
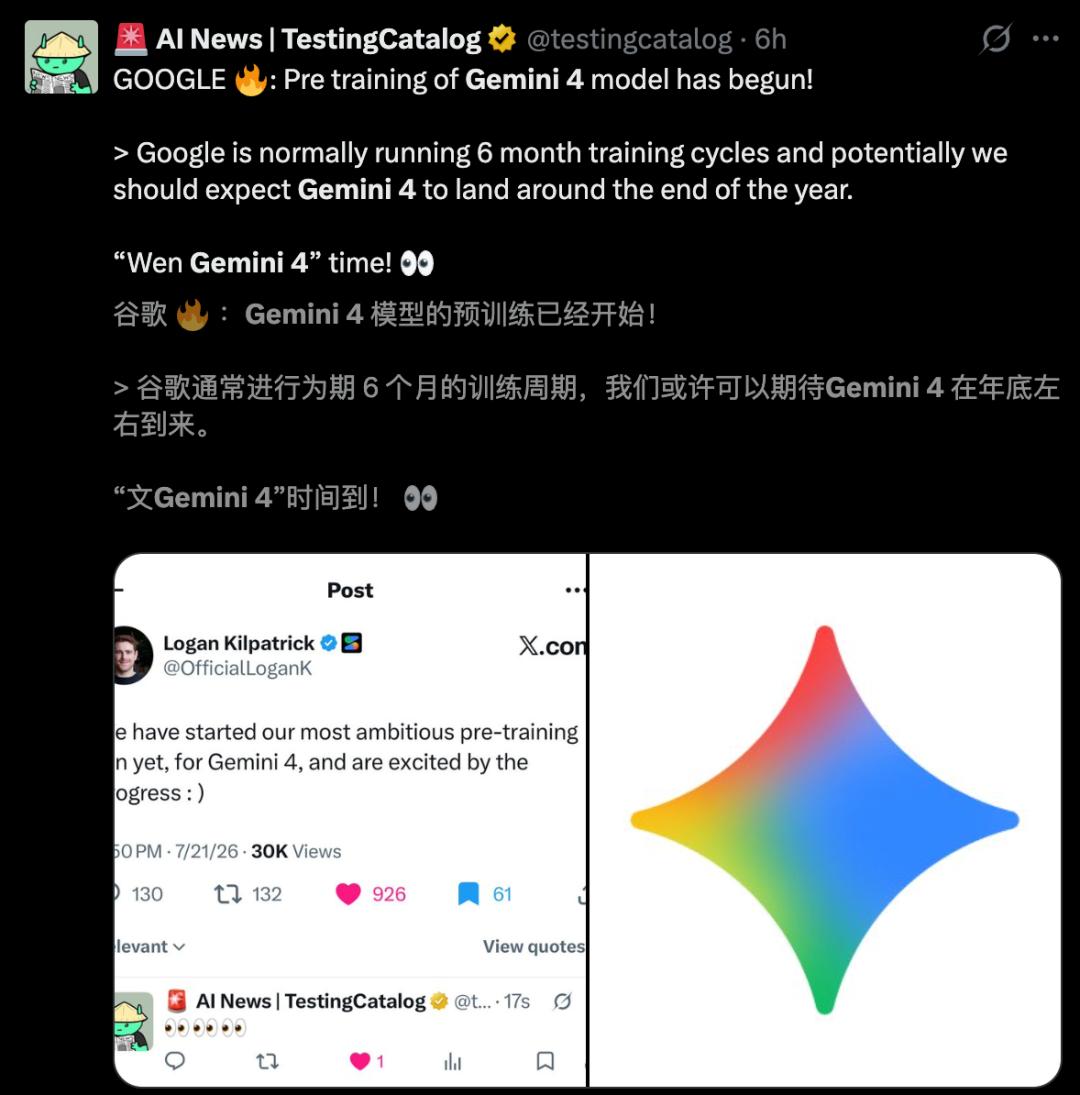
For those of us who pay real money for tokens and build agent systems, there is only one word that really matters in today’s announcement: That is “reduction”.
The price is reduced, token consumption is reduced, and agent execution costs are reduced.
Both the long-awaited flagship model and the newly launched Gemini 4 are “futures” that are not yet available.
Models that are affordable and that can actually be used are the ones that provide tangible value. No matter how powerful your flagship model is, it first needs to be deployed in the real world.
References:
https://blog.google/innovation-and-ai/models-and-research/gemini-models/gemini-3-6-flash-3-5-flash-lite-3-5-flash-cyber/?utm_source=tw&utm_medium=social&utm_campaign=og
This article is from the WeChat official account “AIera”, edited by Taozi, and republished by 36Kr with permission.


