
Image credit: Runway
Joe Russo, director of leading Marvel films such as Avengers: Endgame, predicted in a recent panel interview with Collider that AI will be able to make full-fledged movies within two years. .
I’d say that’s a pretty optimistic schedule. But we are getting closer.
This week, Runway, the Google-backed AI startup that helped develop AI image generation tool Stable Diffusion, released Gen-2, a model that generates videos from text prompts or existing images. (Gen-2 previously had limited access and was on a waiting list.) Gen-2, which follows his Gen-1 model on Runway, which launched in February, is the first to go commercially. It is one of the popular text-to-video models.
“Commercially Available” is an important distinction. Text-to-video conversion is the next frontier in logical generative AI after images and text, and has seen greater focus, especially among tech giants, some of whom have moved from text to video in the past year. I am demonstrating the model to the video. However, these models are still in the research stage and are inaccessible to all but a select few data scientists and engineers.
Of course, the first is not always the best.
Out of personal curiosity and service to you dear readers, I ran some prompts on Gen-2 to get a sense of what the model could and could not achieve. . (Runway now offers about 100 seconds of free video generation.) There weren’t many ways to get rid of my craziness, but the variety of angles, genres that any professional or armchair director would want to see was , tried to capture the style. Silver screens, sometimes even laptops.
One of the limitations of Gen-2 that became immediately apparent was the frame rate of the 4-second video the model generated. It’s pretty low, dropping noticeably to the point of being a slideshow in places.

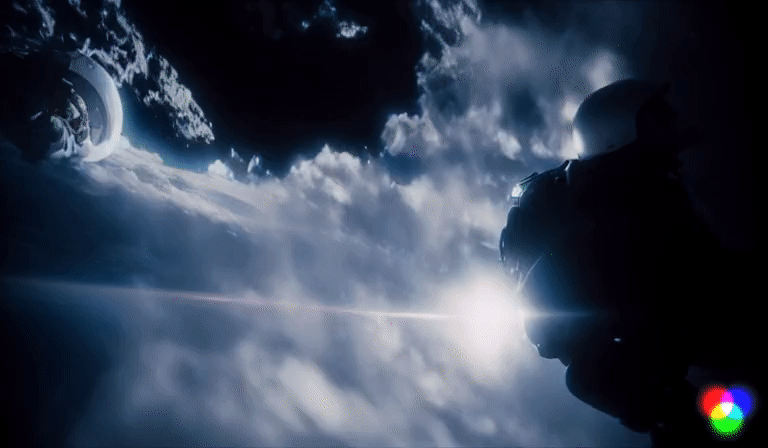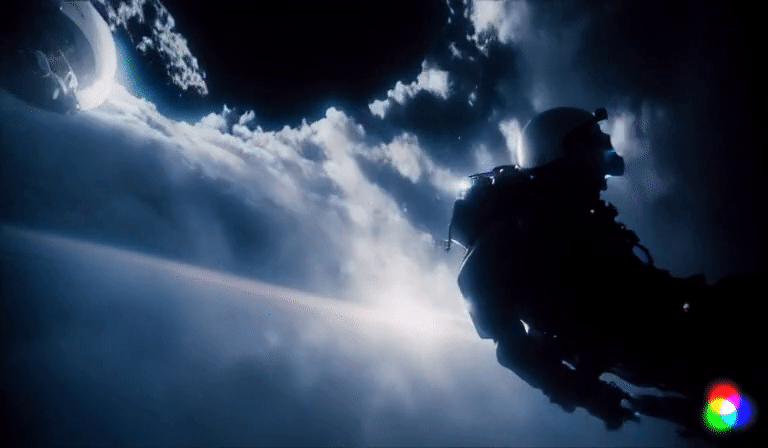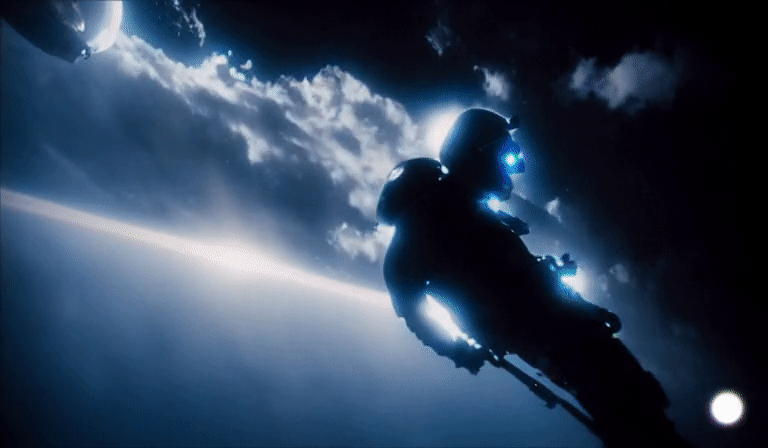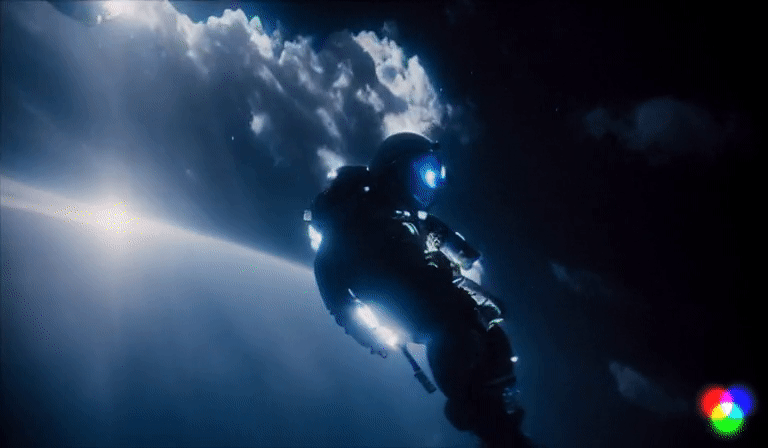
Image credit: Runway
What’s unclear is whether this is a technology issue or Runway’s attempt to save computational costs. Either way, Gen-2 is a seemingly unattractive proposition for editors who want to avoid post-production work.
Beyond framerate issues, Gen-2-generated clips tend to have a certain graininess and ambiguity in common, as if some kind of old-fashioned Instagram filter had been applied. got it. Other artifacts also occur here and there, such as pixelation around objects when the “camera” (for lack of the right word) surrounds them, or when you zoom quickly towards an object.
Like many generative models, Gen-2 is not particularly consistent with respect to physics and anatomy. Like anything surrealism has conceived, the arms and legs of the people in Gen-2’s produced videos merge and separate again, while objects melt and disappear into the floor, their reflections distorting and distorting. . And, upon prompting, the face looks doll-like, with glossy emotionless eyes and pasty skin reminiscent of cheap plastic.
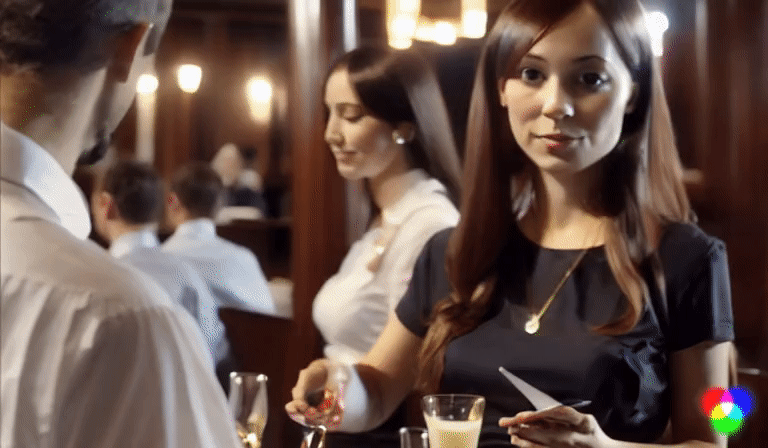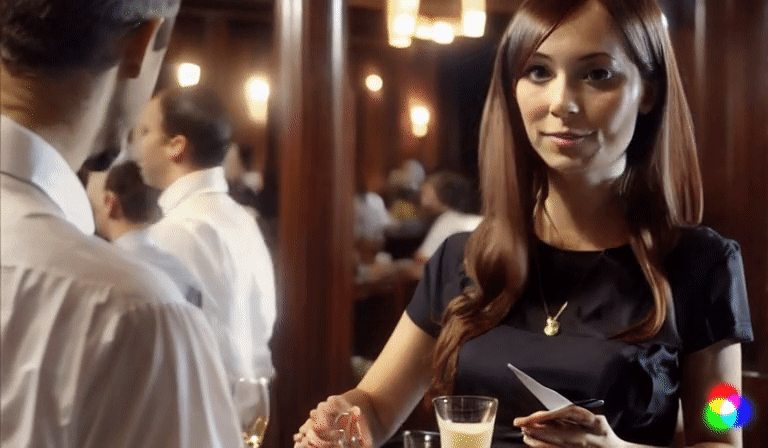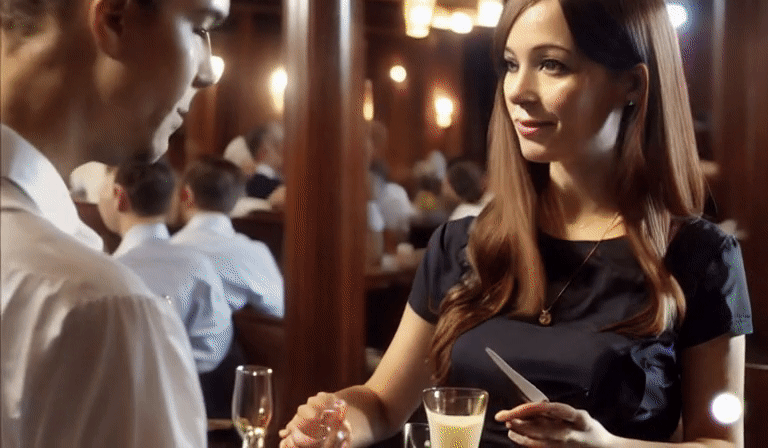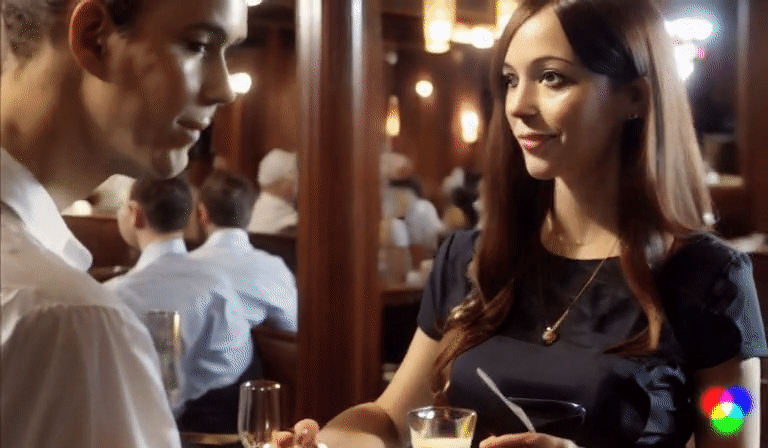
Image credit: Runway
Furthermore, there is also the issue of content. Gen-2 seems to have a hard time picking up on nuances, seeming to stick to certain descriptors in the prompt and randomly ignore others.
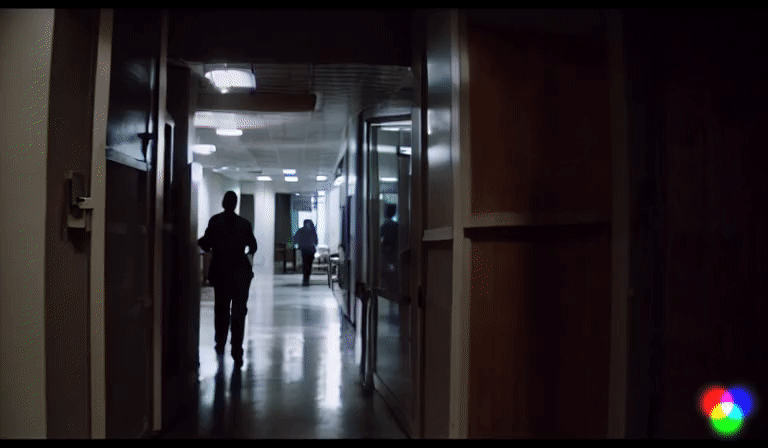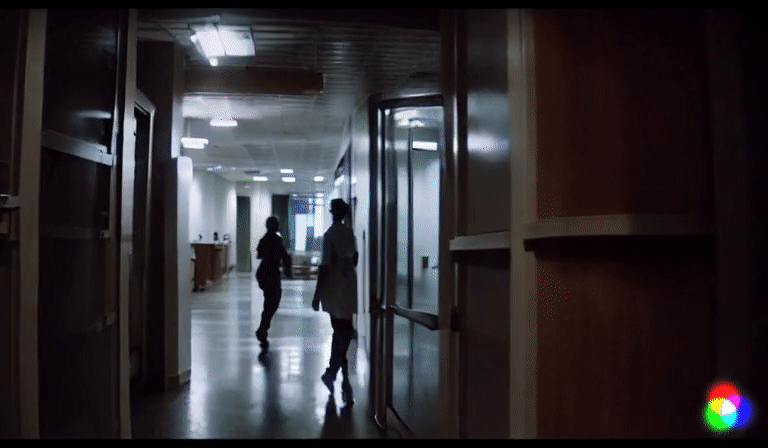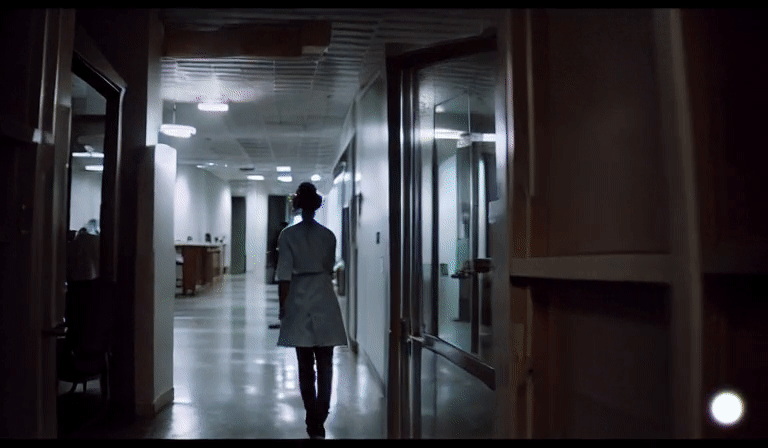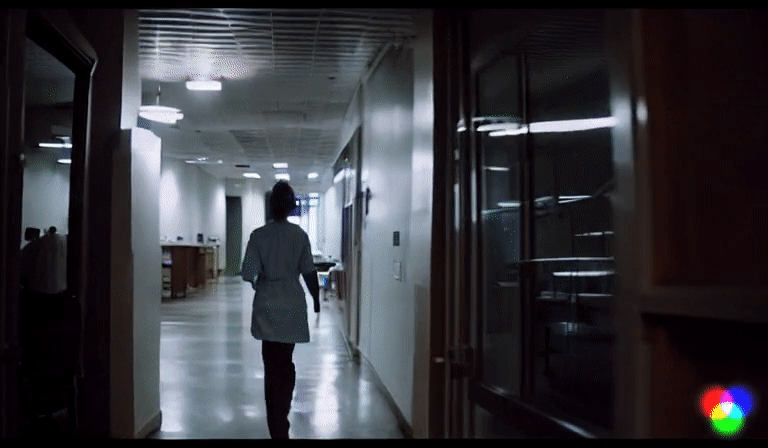
Image credit: Runway
One of the prompts I tried, “A video of an underwater utopia in the style of a ‘found footage’ movie shot with an old camera” did not yield such a utopia. It only brought what looks like first-person scuba diving. An unnamed coral reef. Gen-2 also struggled with other prompts, notably failing to produce shots of him zooming in for prompts that called for a “slow zoom”, failing to fully recreate the look of the average astronaut.
Could the problem be in the Gen-2 training data set? Maybe.
Gen-2, like stable diffusion, is a diffusion model that gradually subtracts noise from a starting image composed entirely of noise to learn how to get progressively closer to the prompt. Diffusion models learn through training on millions to billions of examples. In an academic paper detailing Gen-2’s architecture, Runway said the model was trained on an internal dataset of 240 million images and 6.4 million video clips.
Variety of examples is important. If the dataset does not contain much footage of animations for example, the model lacks reference points and cannot produce animations of reasonable quality. (Of course, animation is a wide field, so the dataset is bottom If you have a clip of anime or hand-drawn animation, the model may not always generalize well. all animation type. )
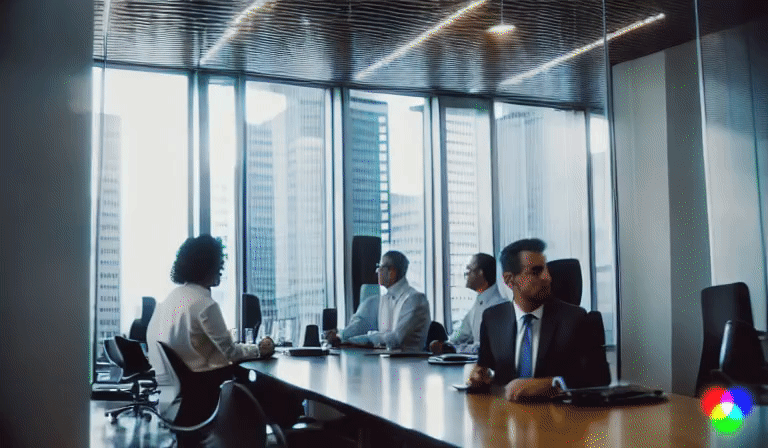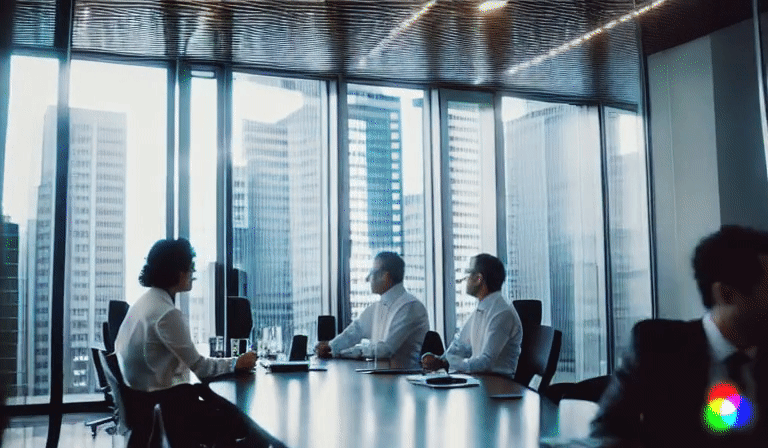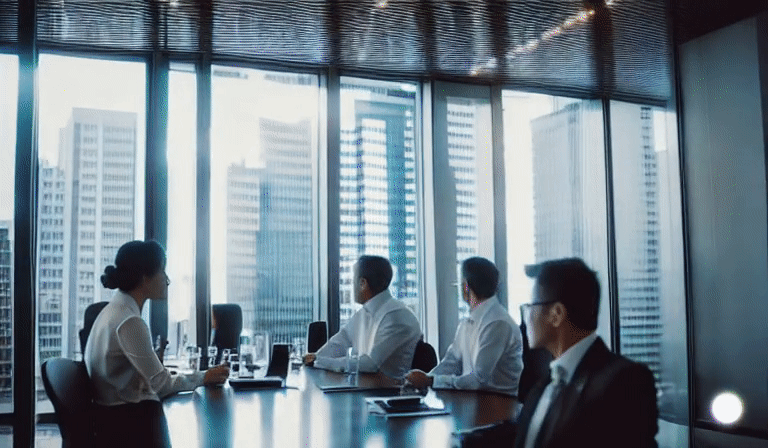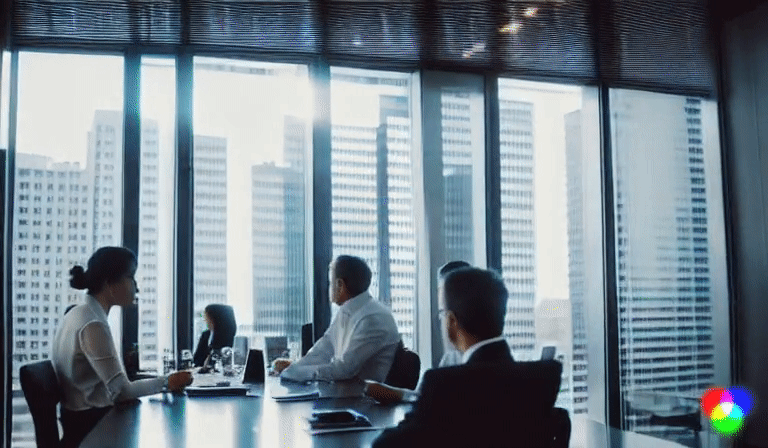
Image credit: Runway
On the plus side, the Gen-2 passed the surface level bias test. Generative AI models like DALL-E 2 have been found to generate images of prestige positions, such as “CEO or director,” depicting predominantly white males and reinforce social prejudices. 2 was only slightly more diverse in its content. At least in my tests it produced that.
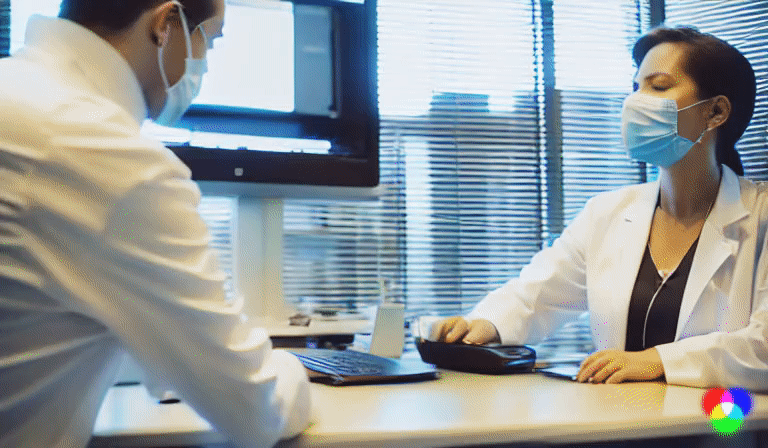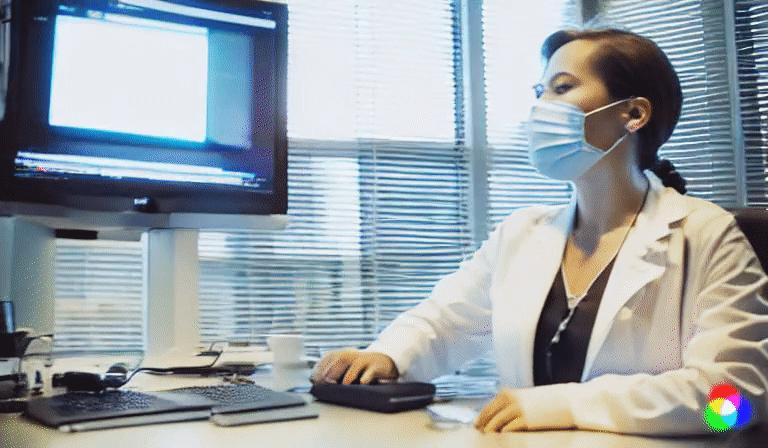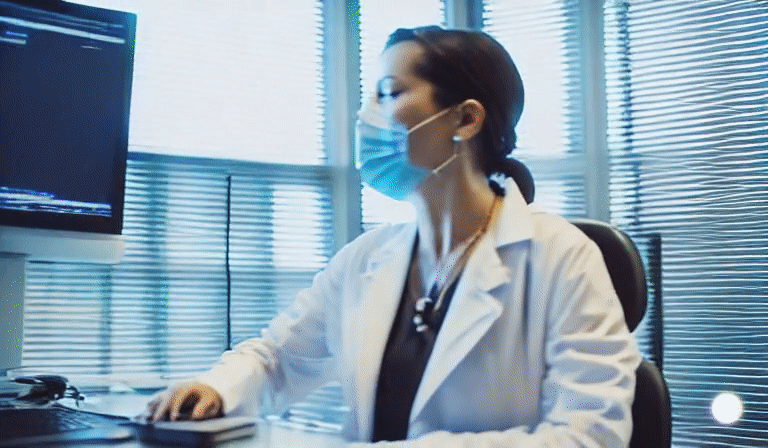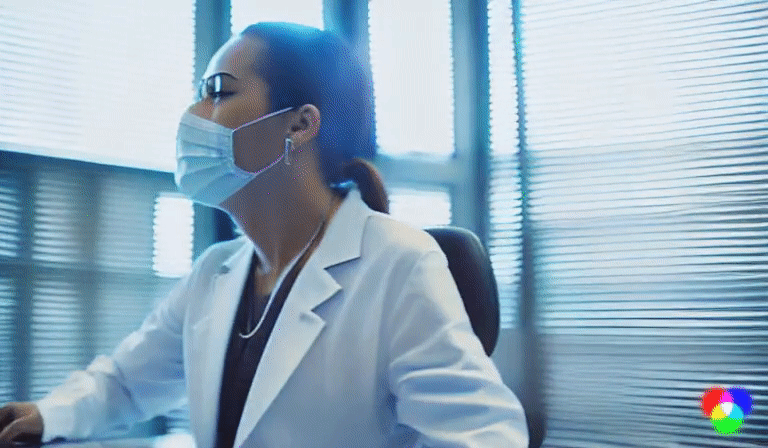
Image credit: Runway
Entering the prompt “Video of CEO entering conference room”, Gen-2 generated a video of a man and a woman (although there are more men than women) sitting around what looks like a conference table. . On the other hand, the output of the prompt “Video of a doctor working in the office” depicts a somewhat Asian female doctor behind the desk.
However, prompts containing the word “nurse” produced less promising results, consistently showing a young Caucasian female. The same goes for the phrase “people waiting for tables.” Clearly, there is work to be done.
For me, the takeaway from all this is that the Gen-2 is more of a novelty or toy than a true tool in your video workflow. Could the output be edited to be more consistent? Maybe. However, some videos may require more work than shooting the footage from scratch.
that shouldn’t happen that too deny technology. His Runway accomplishments here have been impressive, effectively beating tech giants with their text-to-video punch. And I think some users will find uses for the Gen-2 that don’t need photorealism or a lot of customizability. (His CEO of Runway, Cristóbal Valenzuela, recently told Bloomberg that he sees the second generation as a way to give artists and designers tools to assist them in their creative process.)
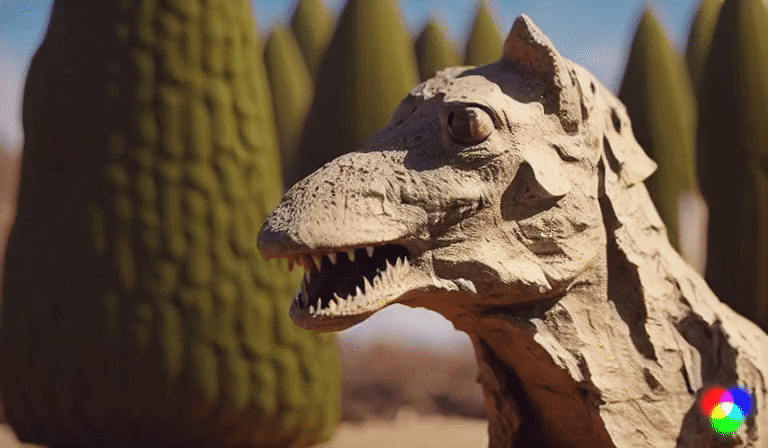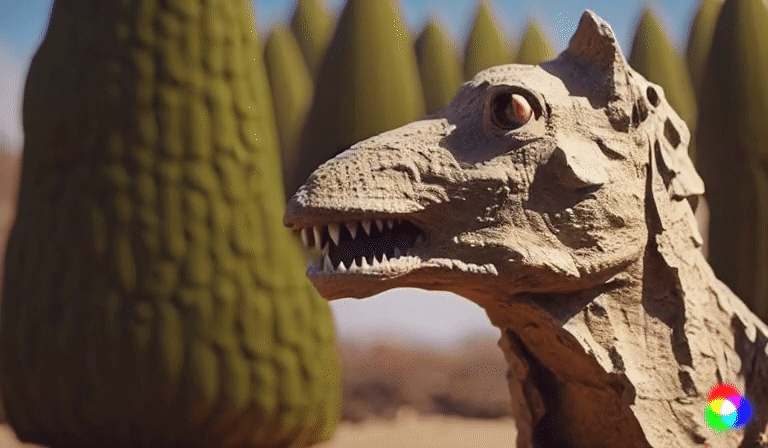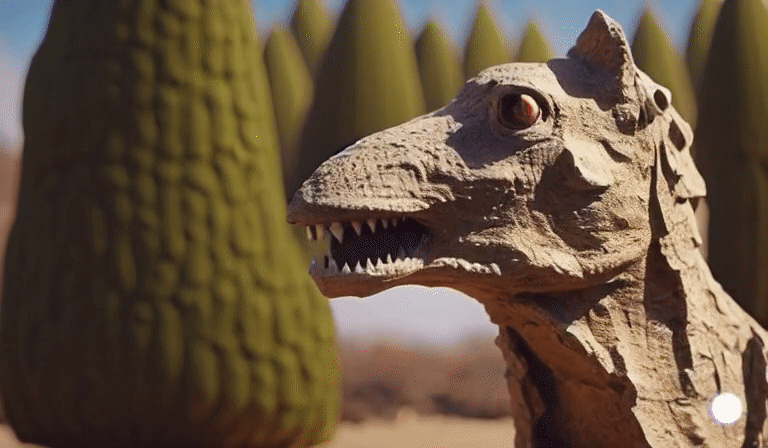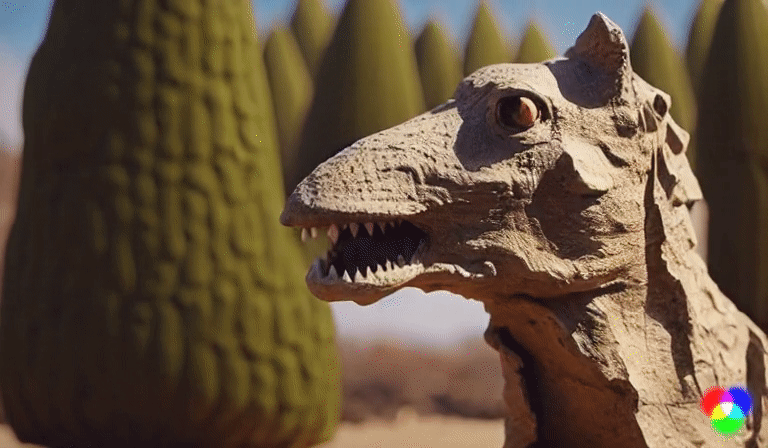
Image credit: Runway
So did I. Gen-2 can really understand different styles that are better suited for lower framerates, like animation and claymation. With a little tinkering and editing, it’s not impossible to stitch together several clips to create a narrative piece.
Not to worry about possible deepfakes, Runway said it combines AI with human moderation to prevent users from generating pornography, violent content, or copyright-infringing videos. I’m here. I could see there was a content filter, but it’s actually an overkill. But of course, these aren’t foolproof methods, so you’ll have to see how well they actually work.
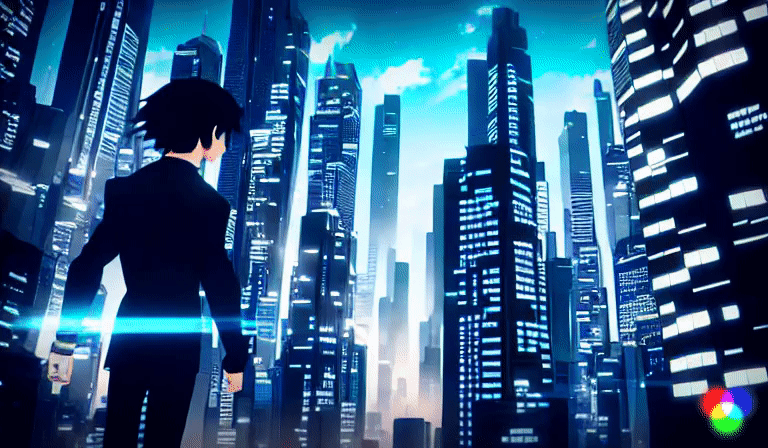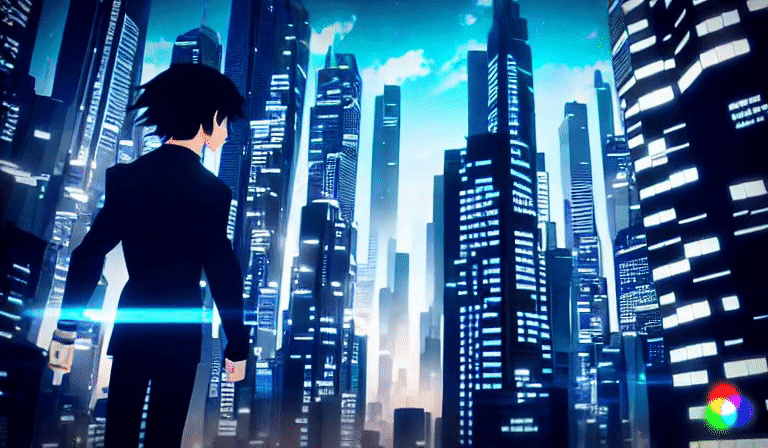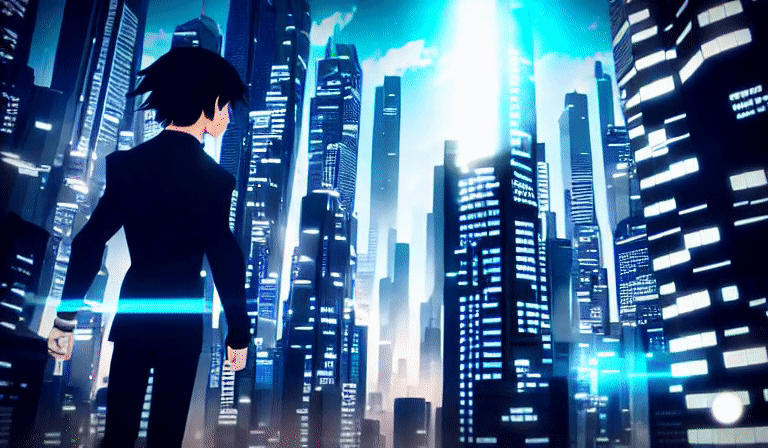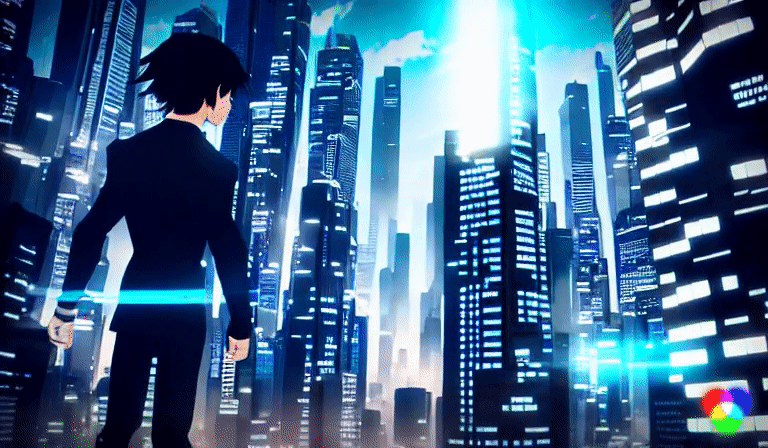
Image credit: Runway
But at least for now, filmmakers, animators, CGI artists, and ethicists can rest easy. It will take at least a few iterations before Runway’s technology comes close to producing cinema-quality footage — assuming it does.