Organizations building custom machine learning (ML) models often have specialized requirements that standard platforms cannot accommodate. For example, healthcare companies need a specific environment to protect patient data while meeting HIPAA compliance. Financial institutions need specific hardware configurations to optimize their own trading algorithms, and researchers need the flexibility to experiment with cutting-edge technologies using custom frameworks. These professional needs encourage you to build custom training environments that allow you to control hardware selection, software versions, and security configurations.
These custom environments provide the necessary flexibility, but create major challenges for ML lifecycle management. Organizations usually try to solve these problems by building additional custom tools, and some teams bring together a variety of open source solutions. These approaches further increase operational costs and require engineering resources that can be used better elsewhere.
MLFLOW Management AI for AWS Deep Learning Containers (DLC) and Amazon Sagemaker AI provide a powerful solution to meet both needs. DLC provides pre-configured Docker containers with frameworks such as Tensorflow and Pytorch, including GPU-supported NVIDIA CUDA drivers. DLC is optimized for AWS performance, maintained regularly to include the latest framework versions and patches, and is designed to integrate seamlessly with AWS services for training and inference. AWS Deep Learning Amis (Dlamis) is a pre-configured Amazon Machine Images (AMIS) for your Amazon Elastic Compute Cloud (Amazon EC2) instance. Dlamis features popular deep learning frameworks such as Pytorch and Tensorflow, available for CPU-based and high-power GPU-accelerated instances. It includes Nvidia Cuda, Cudnn and other necessary tools, and AWS manages Dlamis updates. Together, Dlamis and DLC provide infrastructure and tools to ML practitioners, accelerating deep learning in large-scale clouds.
Sagemaker Managed MLFLOW offers comprehensive lifecycle management with one line of autologging, enhanced comparison capabilities, and complete systematic tracking. As a fully managed service for Sagemaker AI, it reduces the operational burden of maintaining your tracking infrastructure.
This post shows you how to integrate AWS DLC with MLFLOW to create a solution that balances infrastructure controls with robust ML governance. It dramatically reduces the time and resources required to manage your ML lifecycle, while also providing functional setups that your team can use to meet professional requirements.
Solution overview
This section describes the architecture and AWS services used to implement the solution to integrate AWS DLC with Sagemaker Managed MLFLOW. The solution uses several AWS services together to create a scalable environment for ML development.
- AWS DLCS provides pre-configured Docker images with an optimized ML framework
- SageMaker Managed MLFLOW introduces enhanced model registry capabilities with fine-tuned access controls, adding generation AI support through LLM experiments and specialized tracking for rapid management
- Save and manage Amazon Elastic Container Registry (Amazon ECR) container images
- Amazon Simple Storage Service (Amazon S3) stores input and output artifacts
- Amazon EC2 runs AWS DLC
This use case uses integrated Sagemaker Managed MLFlow tracking code to develop a Tensorflow neural network model for Avalon age prediction. Next, subtract the optimized TensorFlow training container from the AWS Public ECR repository and access the MLFLOW tracking server to configure the EC2 instance. Next, you can save the model artifacts in Amazon S3 and run the training process within the DLC while recording the experimental results in MLFLOW. Finally, we view and compare experimental results in the MLFLOW UI to assess the performance of the model.
The following diagram showing the interaction between various AWS services, AWS DLCS, and Sagemaker managed MLFLOW for the solution.
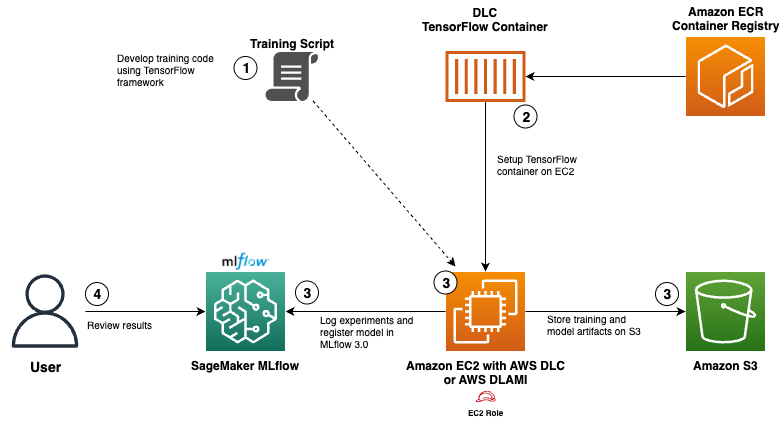
The workflow consists of the following steps:
- We develop a Tensorflow neural network model for age prediction of Avalon. Integrate Sagemaker managed MLFLOW tracking within model code to record parameters, metrics, and artifacts.
- Pulls optimized Tensorflow training containers from the AWS Public ECR repository. Use your EC2 AWS ID and Access Management (IAM) role to access the MLFLOW tracking server to configure Amazon EC2 and DLAMI.
- Run the training process in a DLC running on Amazon EC2, save the model artifacts in Amazon S3, record all experimental results, and register the model in MLFLOW.
- Compare experimental results via the MLFLOW UI.
Prerequisites
To follow this walkthrough, make sure you have the following prerequisites:
- AWS account with billing enabled.
- An EC2 instance (t3.large or higher) running ubuntu 20.4 or later runs at least 20 GB of available disk space for Docker images and containers.
- Docker (latest) installed on your EC2 instance.
- AWS Command Line Interface (AWS CLI) version 2.0 or later.
- The role of IAM with the following permissions:
- SageMaker Managed Amazon EC2 talking to MLFlow.
- Amazon ECR is an Amazon ECR for pulling Tensorflow containers.
- Sagemaker managed MLFLOW to track experiments and register models.
- Amazon Sagemaker Studio domain. To create a domain, see the guide to setup with Amazon Sagemaker AI. I'll add it
sagemaker-mlflow:AccessUIPermissions for the created Sagemaker execution role. This permission allows you to navigate to MLFLOW from the Sagemaker Studio console. - Sagemaker managed an MLFLOW tracking server configured for Sagemaker AI.
- Internet access from EC2 instances to download Abalone datasets.
- The GitHub repository has been cloned into an EC2 instance.
Deploy the solution
Detailed step-by-step instructions are available in the accompanying GitHub repository README file. The walkthrough covers the entire workflow from provisioning the infrastructure to configuring the first training job execution with comprehensive experimental tracking.
Analyze the experimental results
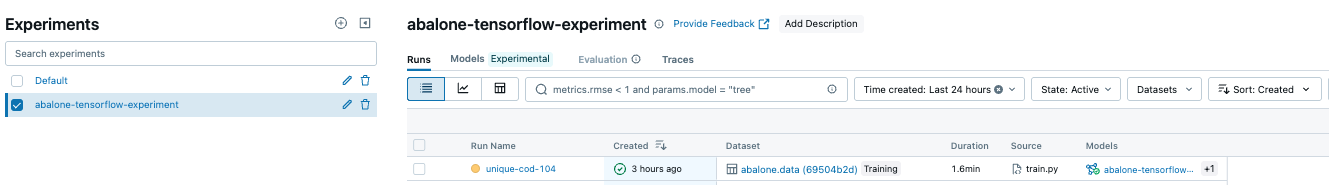
After following the steps in the README file, you can access and analyze the experimental results. The following screenshot shows how Sagemaker Managed MLFLOW offers comprehensive experimental tracking, model governance and auditability for deep learning workloads. Once the training is complete, all experimental metrics, parameters, and artifacts will be automatically captured in MLFLOW, providing a central location to track and compare your model development journey. The following screenshot shows the experiment abalone-tensorflow-experiment It has a name unique-cod-104. This dashboard provides a complete overview of all experimental runs, allowing you to compare different approaches and iterations of models at a glance.
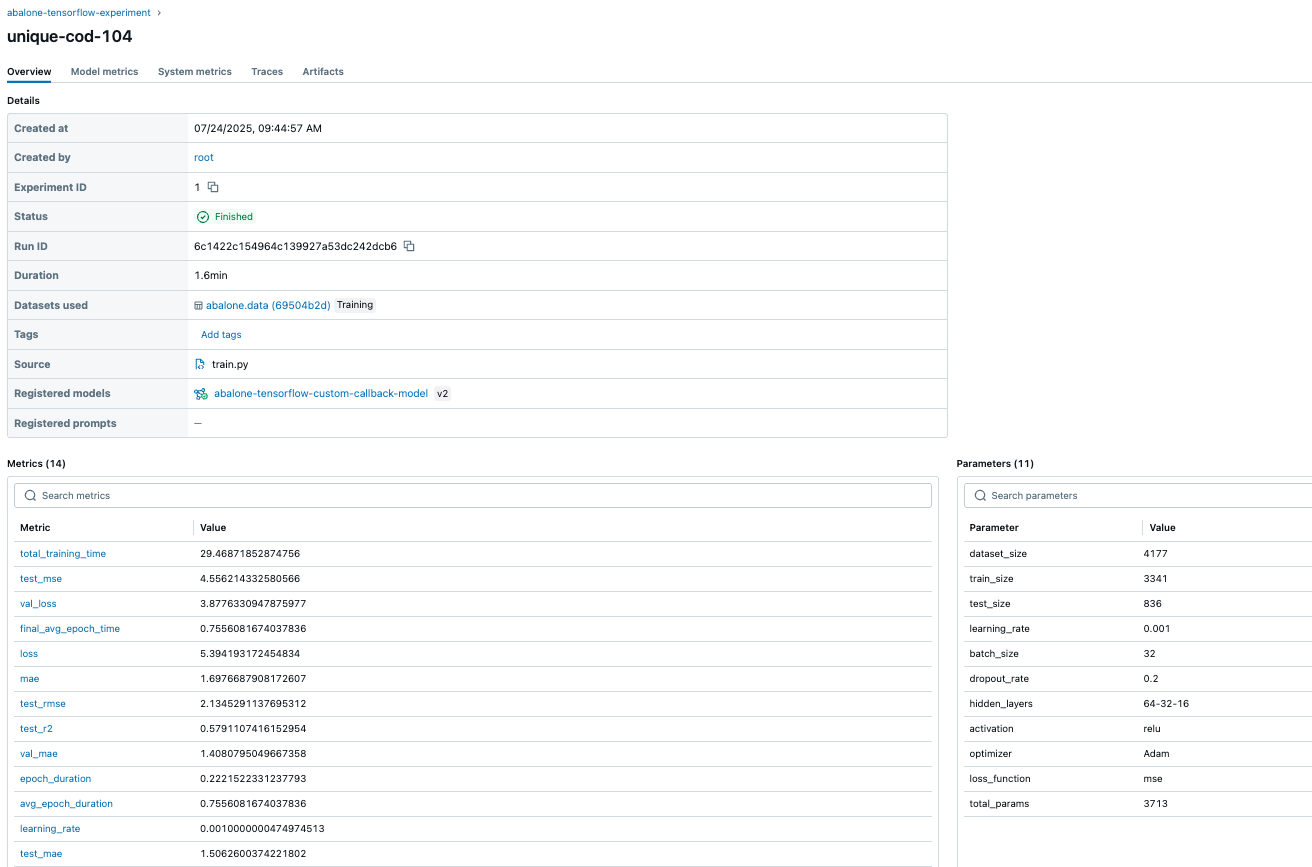
The following screenshot shows detailed information about the run unique-cod-104Includes registered models abalone-tensorflow-custom-callback-model (Version V2). This view provides important information about the origin of the model and shows exactly which experiments have generated a model version, a critical component of model governance.
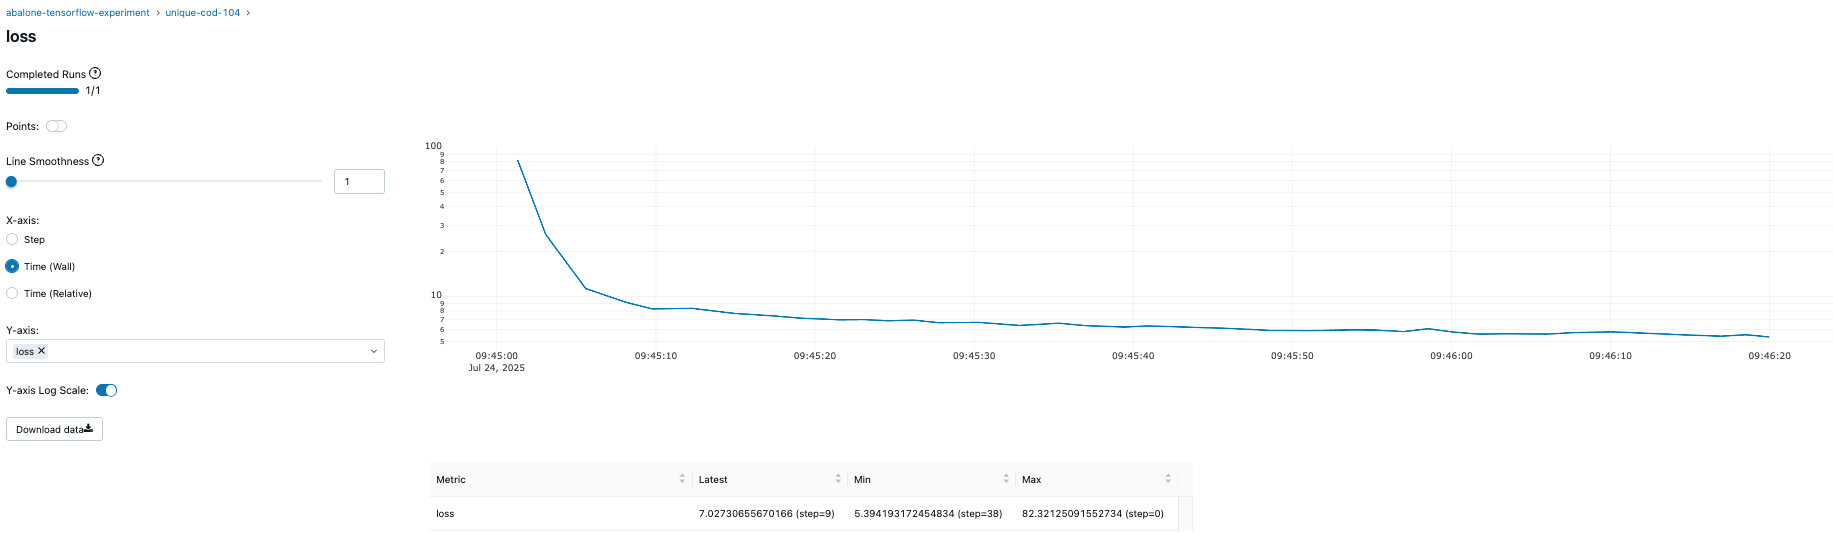
The following visualization tracks training loss across epochs captured using custom callbacks. Such metrics understand model convergence patterns, assess training performance, and provide insight into potential optimization opportunities.
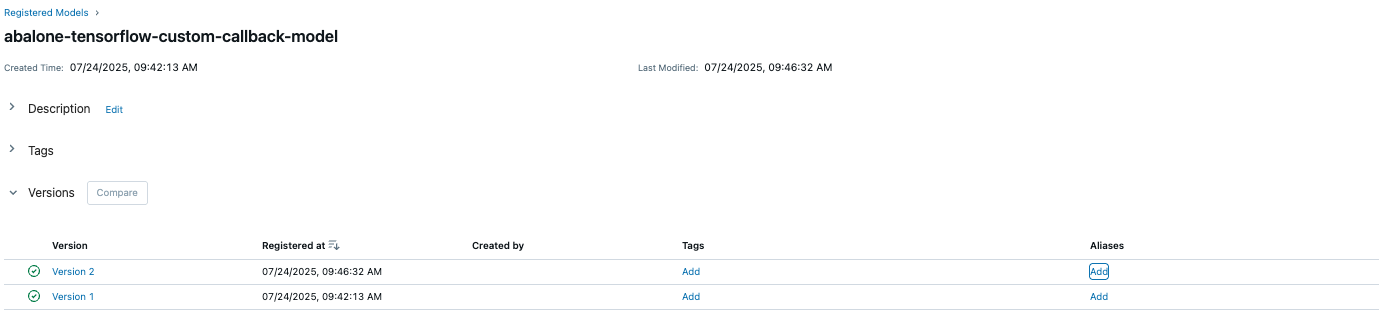
The registered model is displayed as shown in the following screenshot abalone-tensorflow-custom-callback-model Tracked in the model registry. This integration enables versioning, model lifecycle management, and deployment tracking.
The following screenshot shows one of the most powerful governance features of the solution. When recording a model with mlflow.tensorflow.log_model() Using registered_model_name The parameters and models are automatically registered in the Amazon Sagemaker model registry. This creates complete traceability from experiments to deployment models, establishing that the audit trail connecting the training is run directly on the production model.
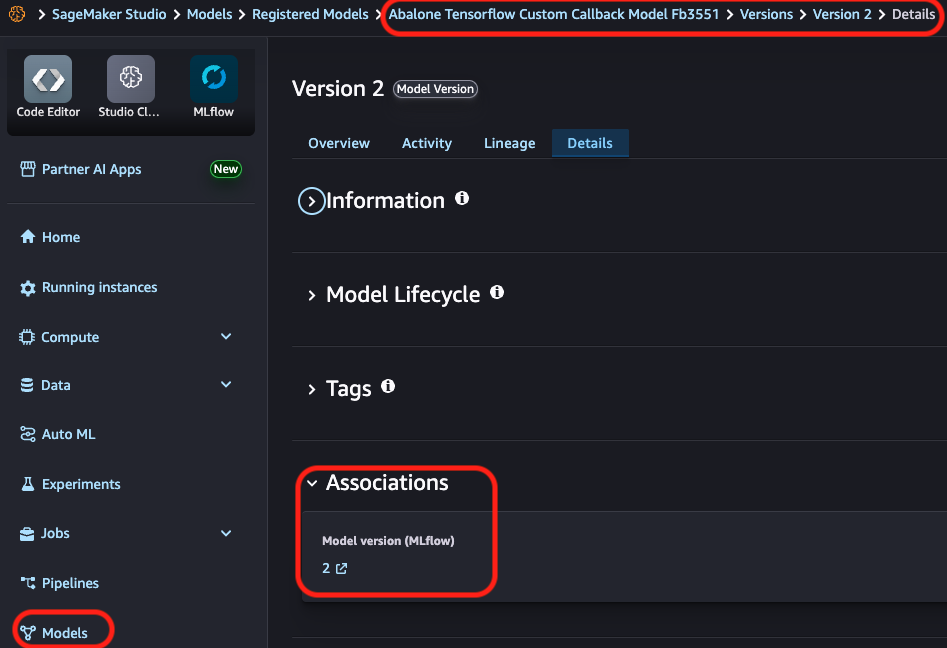
This seamless integration between a custom training environment and the Sagemaker governance tool helps maintain visibility and compliance throughout the ML lifecycle.
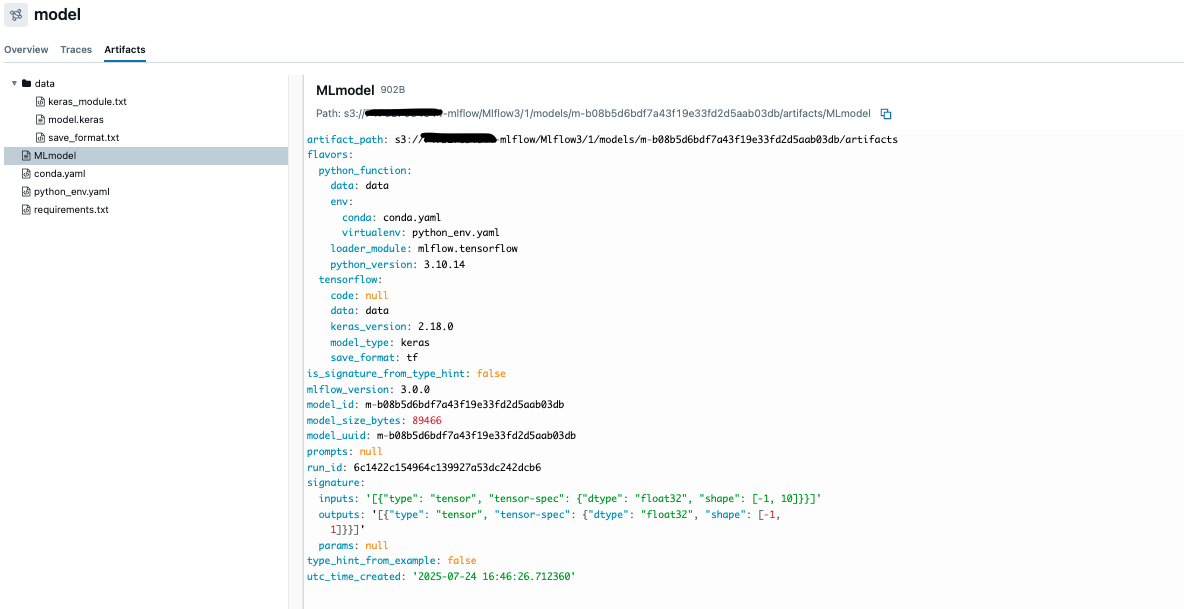
As shown in the following screenshot, the model artifacts will be automatically uploaded to Amazon S3 after training is complete. This organized storage structure ensures that all model components, including weights, configurations, and related metadata, are securely stored and accessible through standardized paths.
Cost impact
The following resources are costly: To estimate costs, see the respective pricing pages.
- Amazon EC2 On Demand – See Provisioned Instance Sizes and AWS Regions. Storage using Amazon Elastic Block Store (Amazon EBS) is additional.
- Sagemaker Managed MLFlow – Details can be found below On-demand pricing For Sagemaker, mlflow for tracking and storage.
- See Amazon S3 – Storage and Request Pricing.
- Sagemaker Studio – There is no additional charge for using the Sagemaker Studio UI. However, there is a cost incurred for attached EF or EBS volumes, jobs or resources started from the Sagemaker Studio application, or JupyterLab application.
cleaning
Complete the following steps to clean up your resources:
- Delete the MLFLOW tracking server. This is because costs continue to be incurred as long as they are running.
- Stop the EC2 instance to avoid any additional costs.
- Delete training data, model artifacts, and MLFLOW experimental data from the S3 bucket.
- Review and clean up the temporary IAM role created for EC2 Instance.
- Delete the Sagemaker Studio domain.
Conclusion
AWS DLCS and Sagemaker Managed MLFLOW provide ML teams with a solution that balances the trade-off between governance and flexibility. This integration helps data scientists seamlessly track experiments and deploy models for inference, and helps administrators establish a secure, scalable Sagemaker managed MLFLOW environment. Organizations can standardize their ML workflows using either AWS DLC or Dlamis, while meeting specialized requirements, ultimately allowing organizations to accelerate their journey to business with greater control and efficiency, from model experimentation to business impact.
In this post, we explored how to integrate a custom training environment with Sagemaker Managed MLFLOW to obtain comprehensive experimental tracking and model governance. This approach benefits from centralized tracking, model registration, and systematic tracking while maintaining the flexibility of your preferred development environment. Integration provides a perfect balance of customization and standardization, allowing teams to innovate while maintaining best governance practices.
Now that you know how to track training in DLCS using Sagemaker Managed MLFLOW, you can implement this solution in your own environment. All code examples and implementation details for this post are available in the GitHub repository.
For more information, see the following resources:
About the author
 Gunjan JainismSouthern California-based AWS Solutions Architect specializes in leading large financial services companies through their cloud transformation journey. He skillfully promotes cloud adoption, optimization, and implementation of well-built best practices. Gunjan's professional focus extends to machine learning and cloud resilience, and he shows a certain enthusiasm. Outside of his professional commitment, he balances with spending time naturally.
 Rahul Easwar He is AWS Senior Product Manager and leads managed MLFLOW and partner AI apps within the Sagemaker AIOPS team. With over 15 years of experience spanning startups into enterprise technology, he leverages his entrepreneurial background and MBAs at the Chicago booth to build a scalable ML platform that simplifies AI adoption for organizations around the world. Connect with Rahul on LinkedIn and learn more about his work on ML platforms and enterprise AI solutions.